
What it is
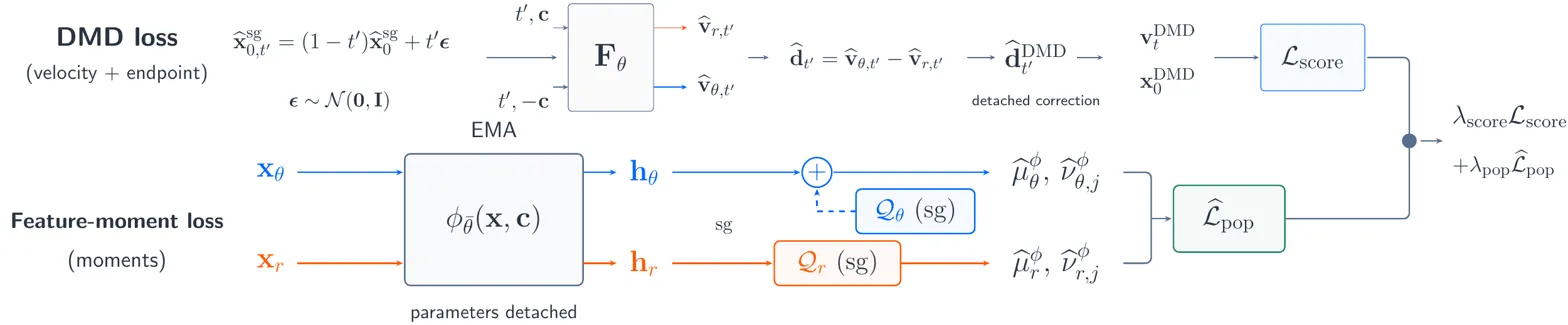
One- and two-step text-to-image generation improved by matching internal feature moments, without an external encoder. One checkpoint serves both 1 and 2 NFE sampling. Generate images in 1 or 2 transformer evaluations while improving long-text rendering by adding feature-moment matching in the generator's own EMA feature space on top of internal DMD.
Key results
- 94.25% LongText-CN and 90.20% LongText-EN at 2 NFE
- 0.25s at 1 NFE and 0.30s at 2 NFE on one A100, BF16
- EMA moment loss adds +0.41 LongText-EN over internal DMD alone
Shows that a generator's own EMA features can replace an external encoder for moment matching in few-step text-to-image distillation.