
What it is
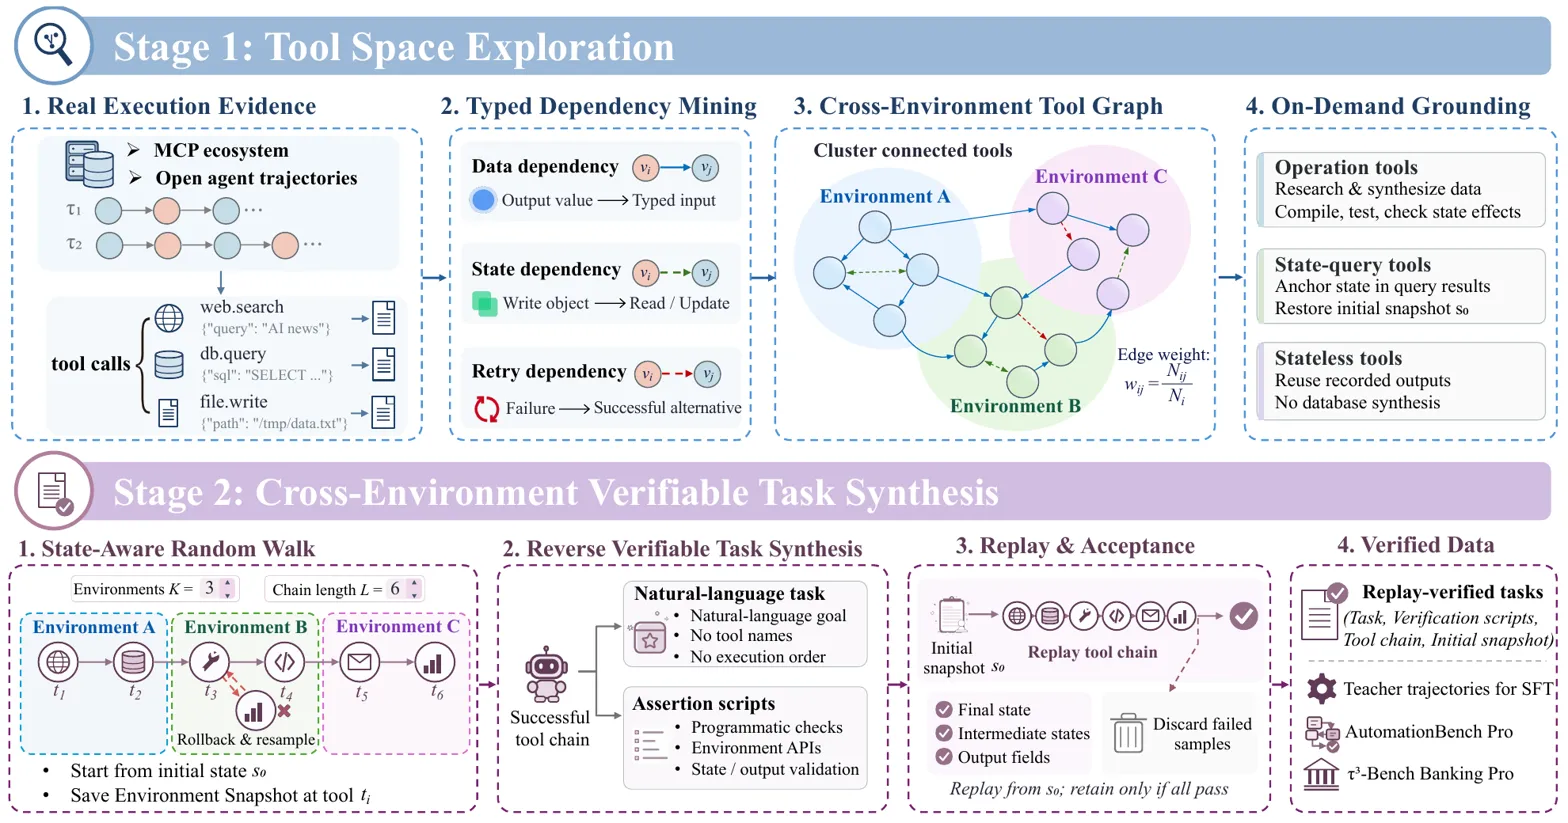
Builds long-horizon agent environments from real tool traces instead of synthetic databases, then synthesizes replay-verified cross-environment tasks and harder benchmark variants. Instead of deriving tools from synthetic data, it starts from real execution traces: mine witnessed tool dependencies, cluster them into environments, synthesize state only when needed, then sample replay-verified cross-environment tool chains.
Key results
- Qwen3.6-35B-A3B improves from 23.0 to 41.0 avg; 43.2 with RL
- GLM-5.2 improves from 44.6 to 56.6 avg across 7 benchmarks
- On Pro benchmarks, 7 frontier models drop by up to 38.2 points
Real execution-witnessed tool composition is a stronger primitive for training and benchmarking long-horizon agents than synthetic, LLM-judged environment graphs.