
What it is
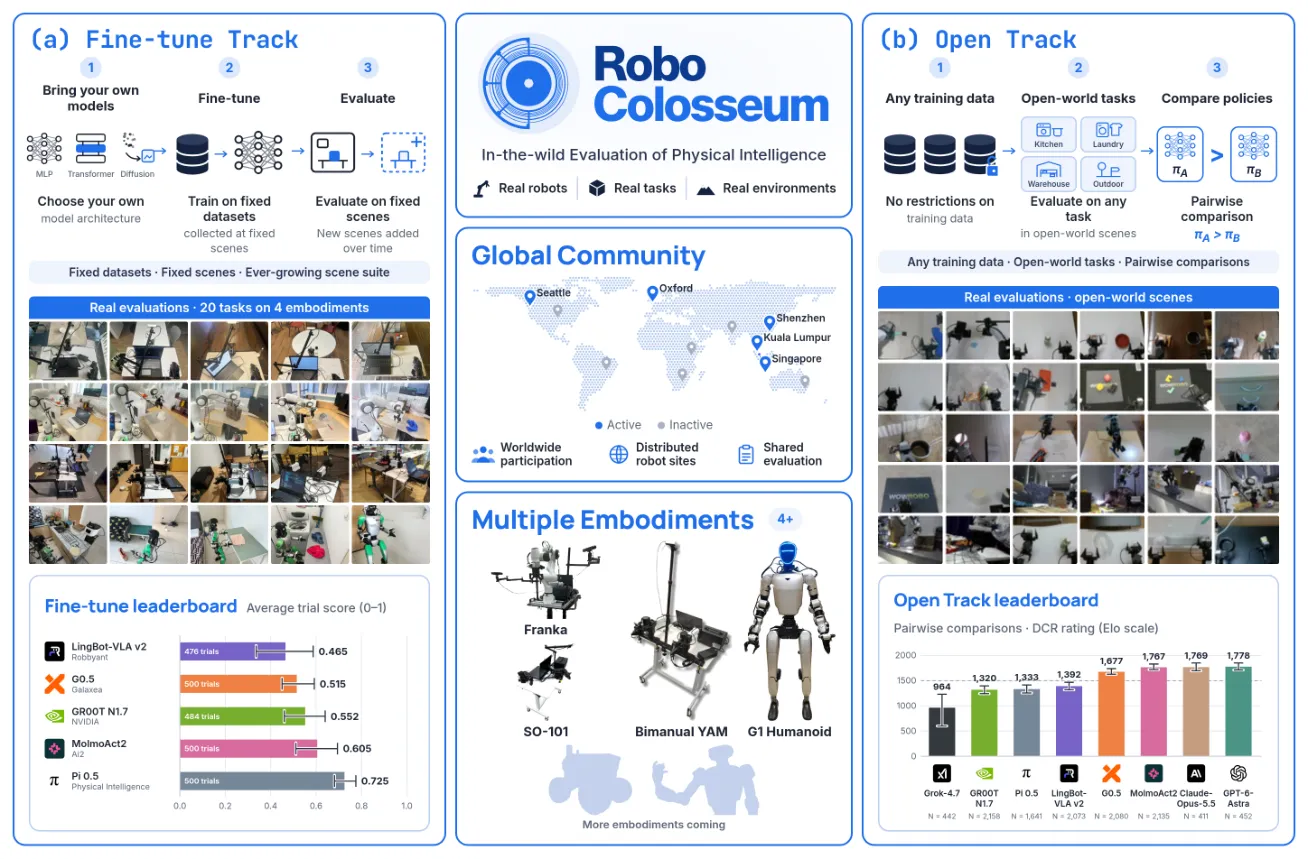
A distributed real-world benchmark for evaluating robot foundation policies across sites, tasks, and embodiments with zero-shot and fine-tuning tracks. Instead of single-site fixed benchmarks, it runs blinded pairwise physical trials across distributed robots plus a controlled fine-tune track, separating zero-shot generalization from adaptation and measuring partial progress, not just success.
Key results
- 5,699 Open Track comparisons collected across 124 sites
- Active matchmaking reached ~90% ranking agreement in 400-500 evals vs ~1,000 uniform
- Cross-embodiment ranking agreement is weak: Kendall's W = 0.24
Real-world robot rankings depend strongly on embodiment and adaptation setting, so scalable distributed evaluation is needed to measure generalization reliably.