Repo

livenerf

Tracks post-release capability drift with a daily locked eval panel, pinned CLI, exact grading, and paired windowed analysis against baseline.

GitHub ↗Sep 22, 2026Paper ↗

  • llm
  • evals
  • benchmarking
  • capability-drift
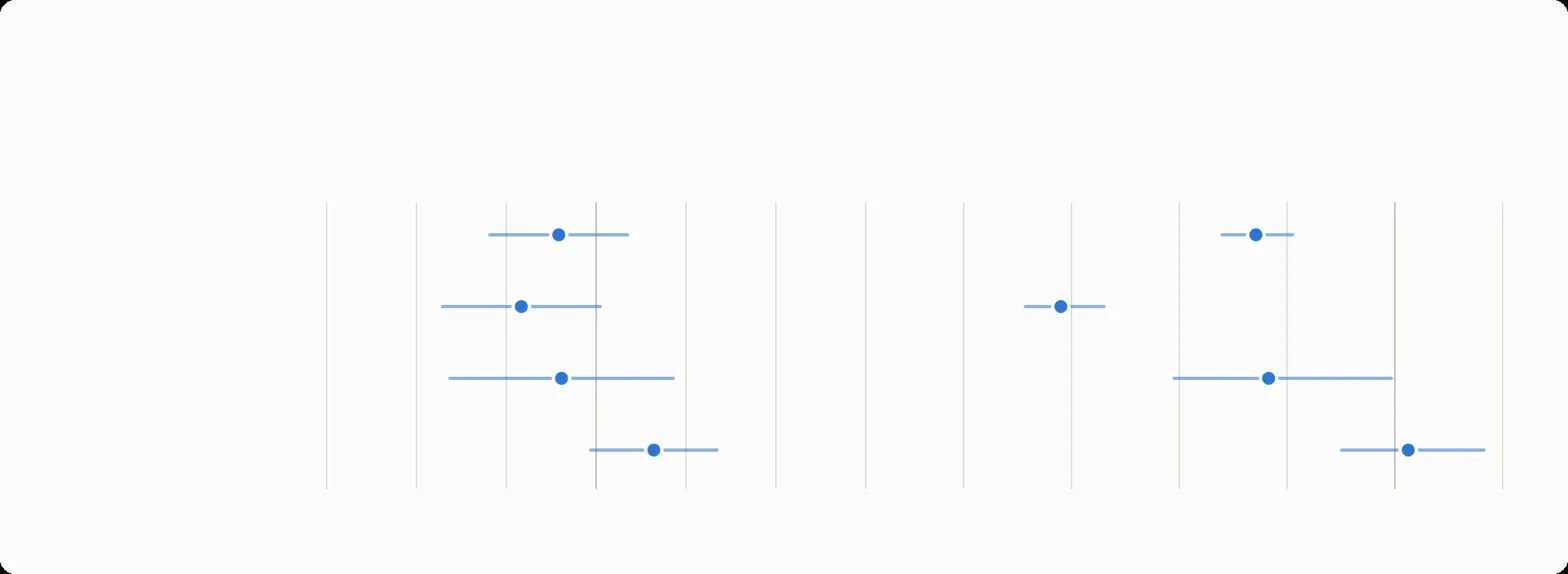
Forest plot showing point estimates with confidence intervals, likely core comparative results

What it is

Append-only benchmark that tracks whether a shipped frontier model drifts in capability over time using pinned prompts, exact graders, and pre-registered stats. Measure whether a deployed Claude model gets worse after launch by running a locked daily panel through a pinned Claude Code harness, logging raw transcripts, and comparing 10-day windows to launch-week baseline.

Key results

  • Uses a 78-item panel selected from 2,336 screened questions
  • Detects ~7.5-point accuracy shifts per 10-day window at planned budget
  • Validation: effort low caused -62% output tokens and -8.3±4.5 accuracy pts

Shows that post-launch model drift can be monitored credibly with a fixed harness, append-only logs, and pre-registered paired evals.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.