
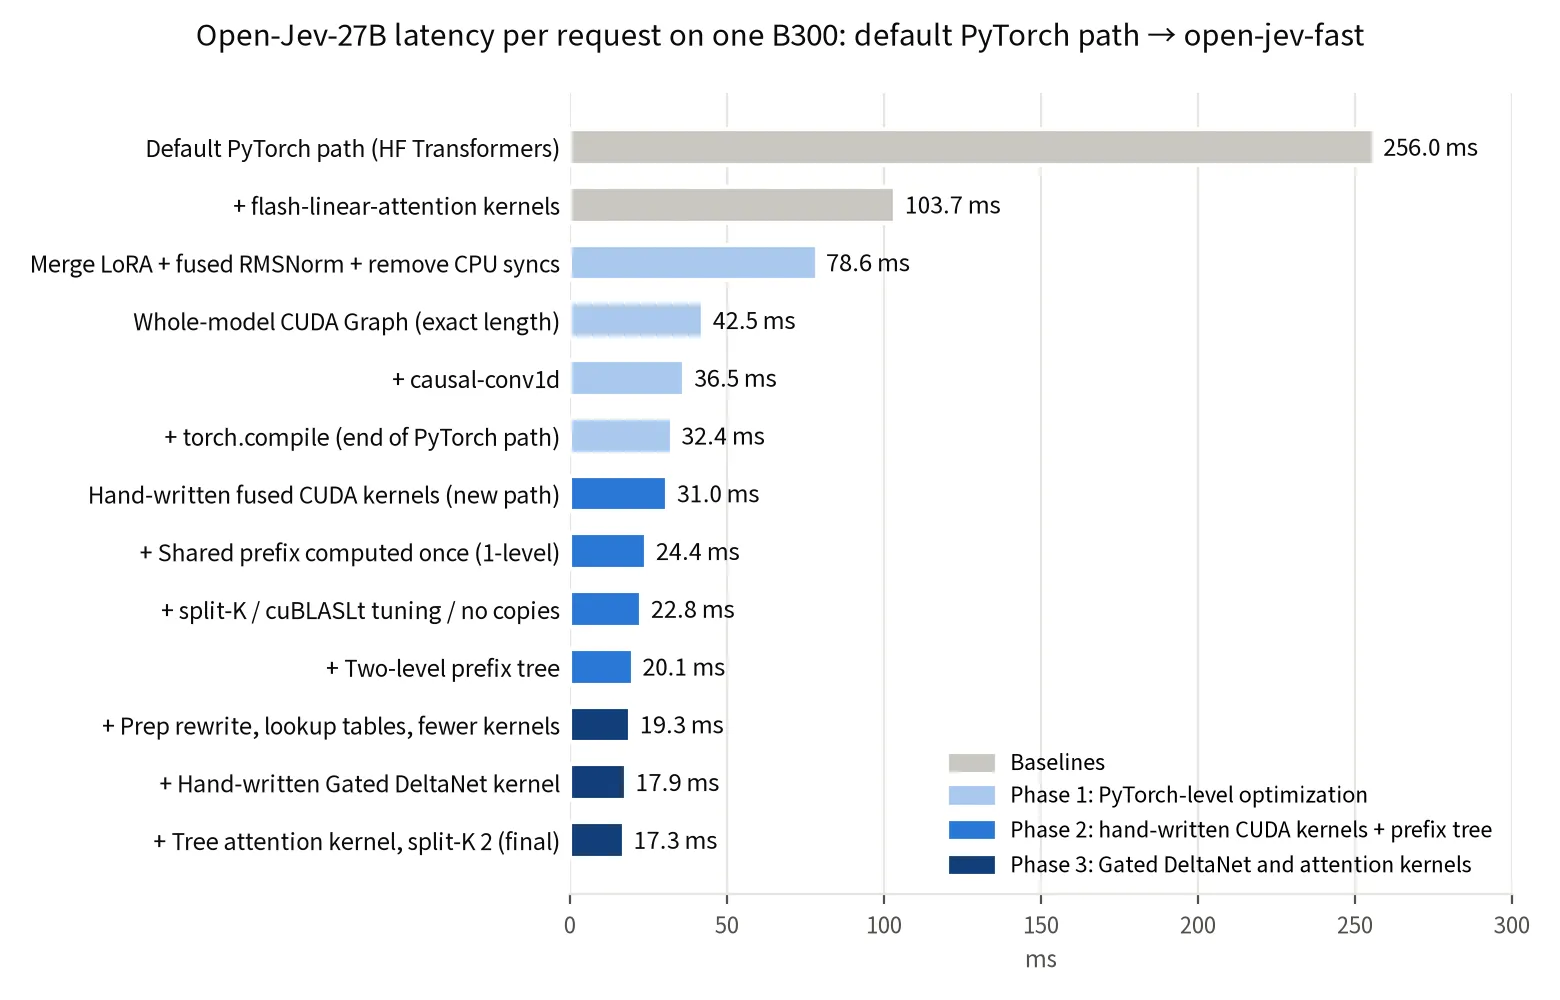
What it is
Drop-in local inference backend for Open-Jev-27B that replaces the forward pass with specialized CUDA kernels, prefix-tree prompt sharing, and CUDA Graphs for much lower latency. Runs Open-Jev-27B with the same server API but much lower latency by computing shared prompt prefixes once and replacing most layer work with fused CUDA kernels and cached CUDA Graphs.
Key results
- 42.0 ms mean JevBench latency vs 258 ms with Open-Jev+FLA
- 17.3 ms on a 539-token example vs 103.7 ms with Open-Jev+FLA
- Keeps JevBench accuracy at 197/231 vs 198/231 for the baseline
Shows that a model-specific backend can turn a CPU-launch-bound LLM server into a much lower-latency system without changing the model or quantizing it.