Repo

esp32-ai

Runs text generation fully on an ESP32-S3 by keeping most model weights in flash and reading only a few embedding rows per token.

GitHub ↗Jul 23, 2026Paper ↗

  • llm
  • microcontroller
  • quantization
  • on-device-inference
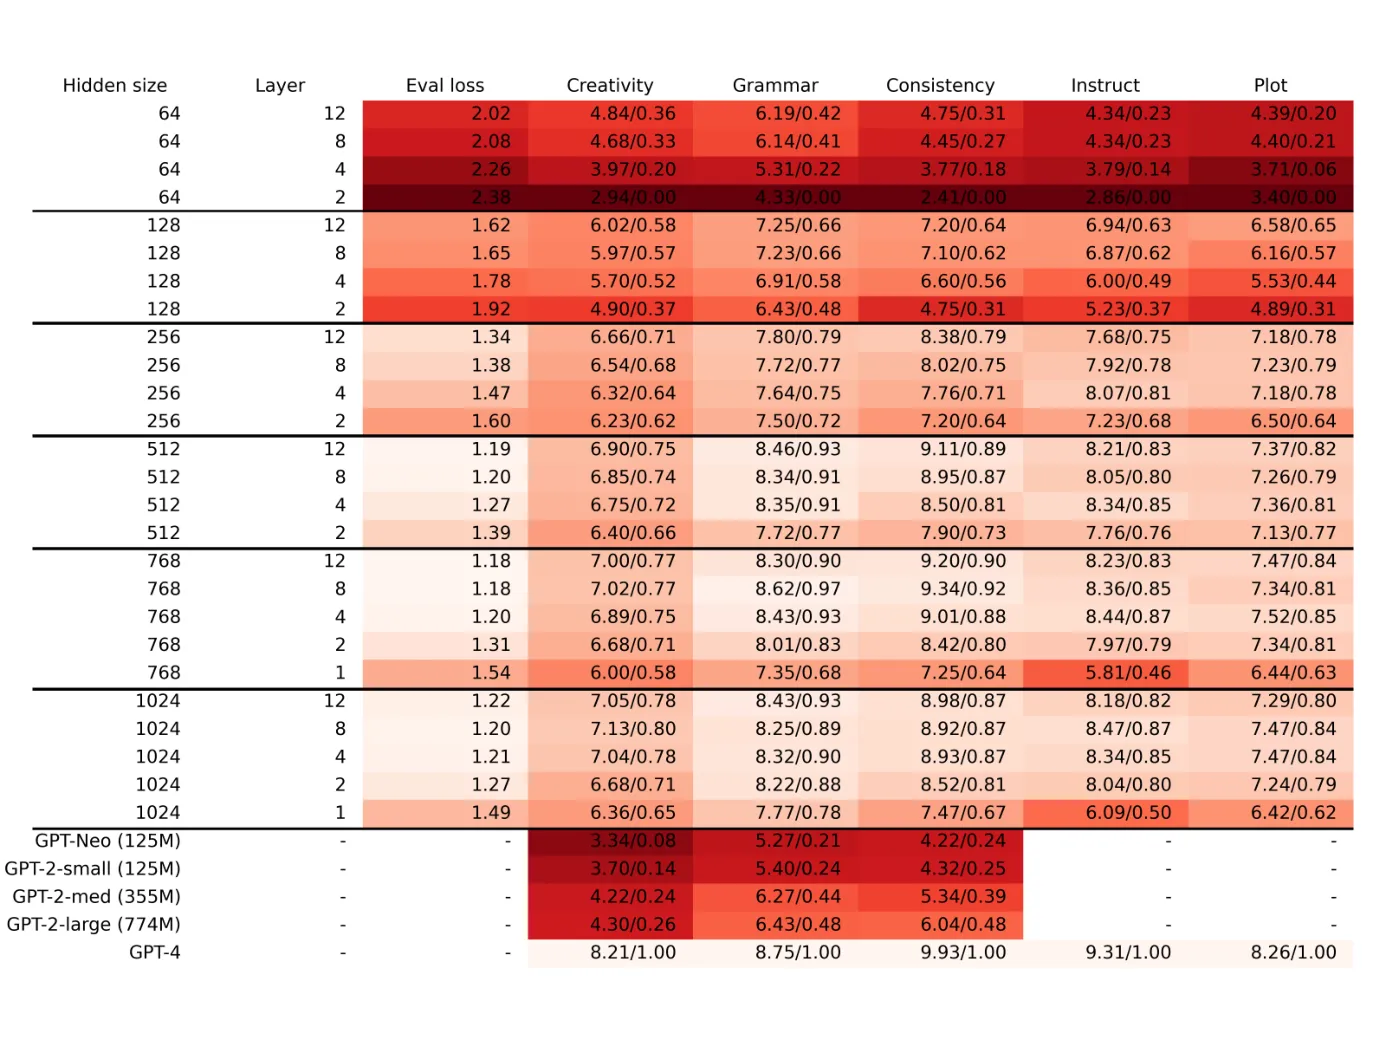
Comparative results table showing model scaling vs baselines across metrics, core claim

What it is

Runs a 28.9M-parameter TinyStories LLM fully on an $8 ESP32-S3 by keeping most weights in flash and streaming only needed rows per token. Run a quantized 28.9M language model entirely on an ESP32-S3, storing a 25M-parameter lookup table in flash and fetching only the rows needed per token.

Key results

  • 28.9M params on ESP32-S3 with 512KB SRAM, 8MB PSRAM, 16MB flash
  • ~9.5 tok/s end to end; ~9.7 tok/s pure compute on-device
  • 25M params stay in flash; about 6 rows and ~450B read per token

Shows that tens-of-millions-parameter LLM inference is feasible on a low-cost microcontroller by treating flash as sampled model storage.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.