
What it is
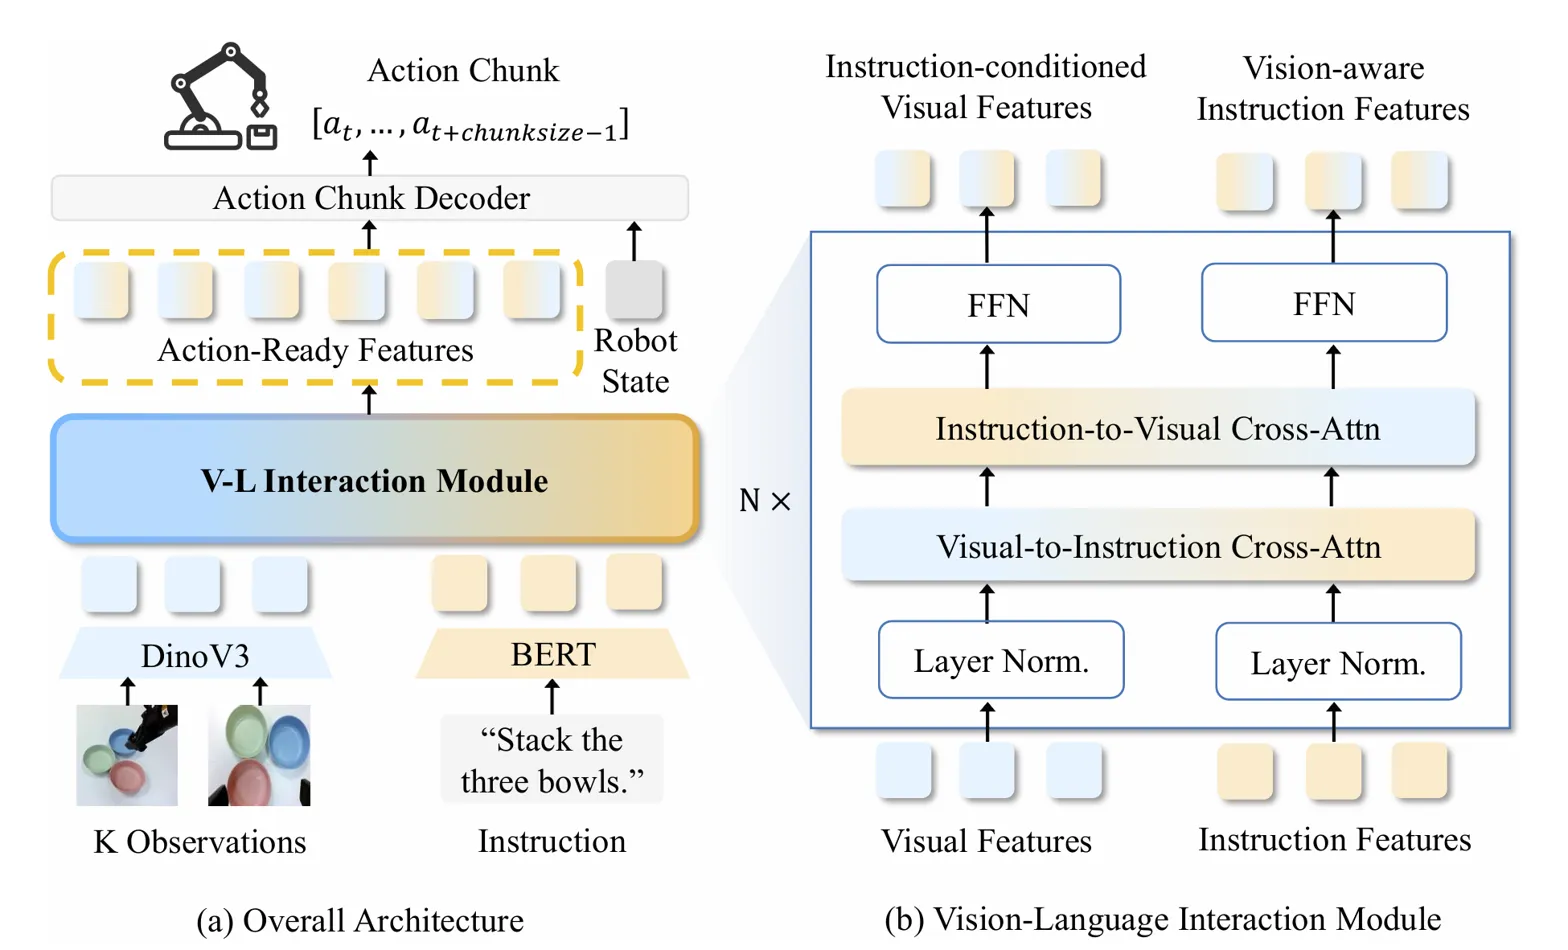
Directly maps vision and language to robot actions, dropping the LLM core for real-time VLA control. It runs at 32 Hz on an RTX 4090 with under 1 GB VRAM. Instead of routing every control step through an LLM, it separately encodes images and text, fuses them with lightweight bidirectional cross-attention, and predicts continuous action chunks in one pass.
Key results
- 97.7% avg success on LIBERO with only 0.2B parameters
- 31.2 ms policy latency on RTX 4090, enabling 32 Hz action updates
- 0.9 GB inference VRAM while matching or beating larger VLA policies
Execution-level robot control does not need an LLM bottleneck; direct vision-language fusion can keep accuracy while drastically cutting inference cost.