
What it is
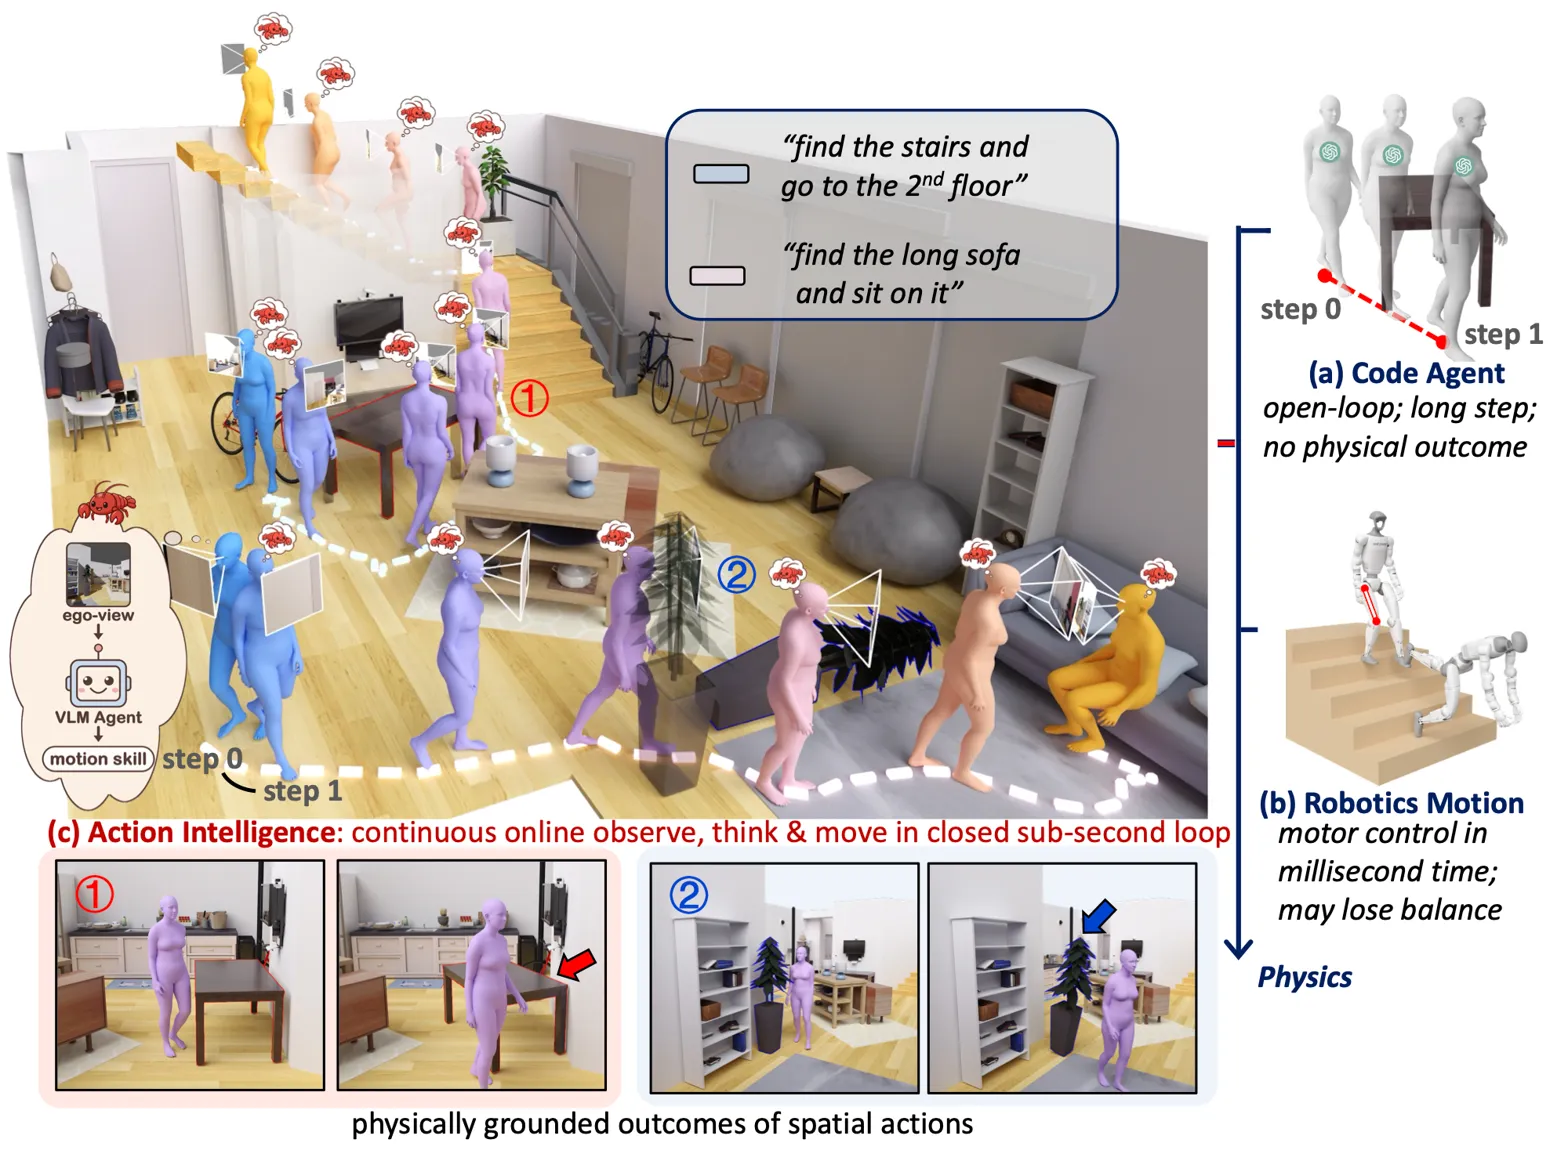
An evaluation framework that lets off-the-shelf VLMs control a humanoid via atomic whole-body skills while factoring out motor failures to measure decision quality. Instead of judging VLM agents through brittle low-level control or scripted actions, it decouples decision-making from execution: a VLM picks atomic skills, a motion generator realizes them as physical full-body motion, and failures are attributed to the decision layer.
Key results
- Best of 9 frontier VLMs reaches only 16.8% success on HumanCLAW-Bench
- Benchmark has 1,218 long-horizon episodes across 41 indoor scenes
- Strongest model's reported target-seeing is within 5 points of true visibility
The main bottleneck for current VLM agents is embodied self-awareness, not object recognition.