Repo

CLM

Ranks candidate actions for a state and answers typed closed-set questions by scoring state-action alignment with cached reusable embeddings.

GitHub ↗Sep 23, 2026

  • llm
  • contrastive-learning
  • verifier
  • tool-calling
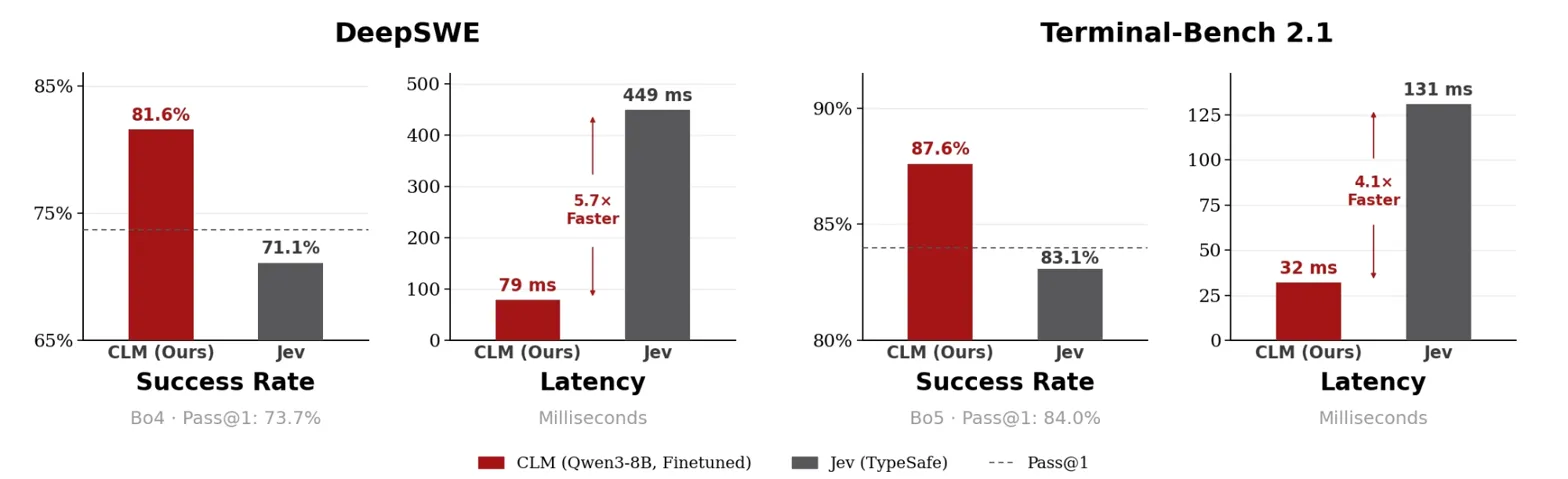
Compares method vs baseline on success rate and latency across two benchmarks

What it is

Serves a contrastive language model that scores actions against states for typed decisions, ranking, and verifier use with much lower latency than Jev. Score candidate actions against a state, then use the same primitive for typed questions, best-of-N ranking, tool routing, and verifier selection through a local API or in-process engine.

Key results

  • Up to 9× lower latency than Jev on computer-use, gaming, tool-calling
  • Verifier fine-tuning hits 87.6% Terminal-Bench 2.1 and 81.6% DeepSWE
  • Repeated-state serving drops p50 from 1.7-2.0 ms to 0.6-0.7 ms on RTX 4090

Shows that contrastive state-action scoring can replace generative selection for many agent decisions while being much faster.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.