Repo

Video-ChatGPT

Answers questions and holds conversations about videos by combining language generation with spatiotemporal video understanding. Includes training and eval tooling.

GitHub ↗Jul 21, 2026Paper ↗

  • multimodal
  • video-qa
  • instruction-tuning
  • benchmarking
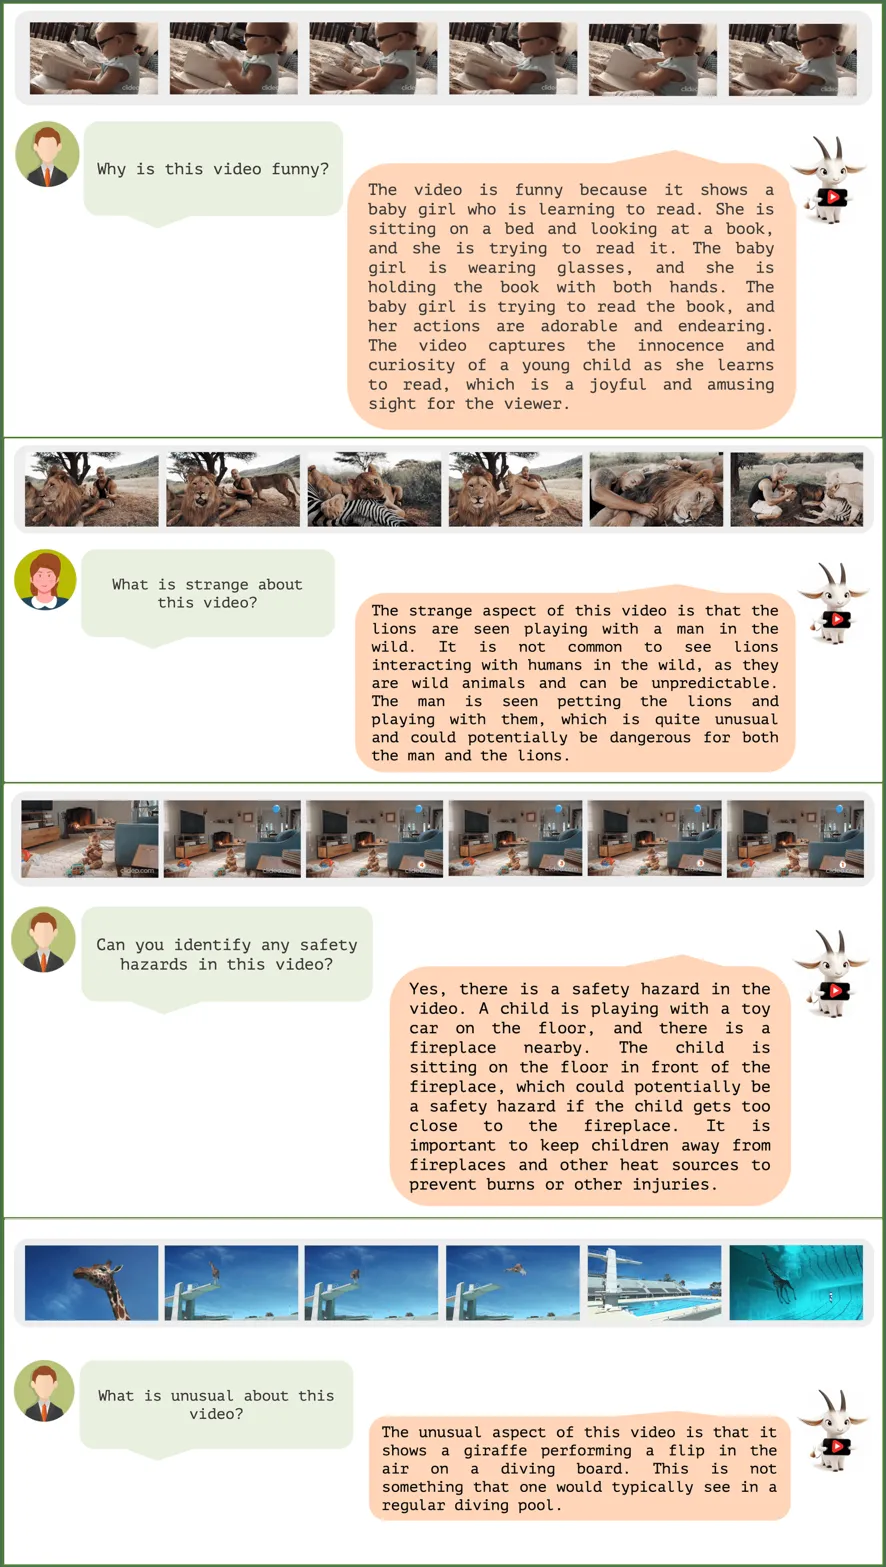
Multiple video QA examples showing model's outputs, demonstrating the work's capabilities

What it is

Video conversation model for detailed QA and dialogue over videos, plus a benchmark and 100K instruction dataset for evaluating video-chat systems. Generate multi-turn conversations and answers about uploaded videos using an LLM paired with spatiotemporal video features, with released training data and evaluation scripts.

Key results

  • Releases 100K video-instruction pairs for training
  • Best zero-shot QA: 64.9 MSVD-QA, 49.3 MSRVTT-QA, 51.4 TGIF-QA
  • Adds quantitative benchmarking over correctness, detail, context, time, consistency

Shows that instruction-tuned LVLMs can be extended from images to useful video conversation with measurable gains.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.