
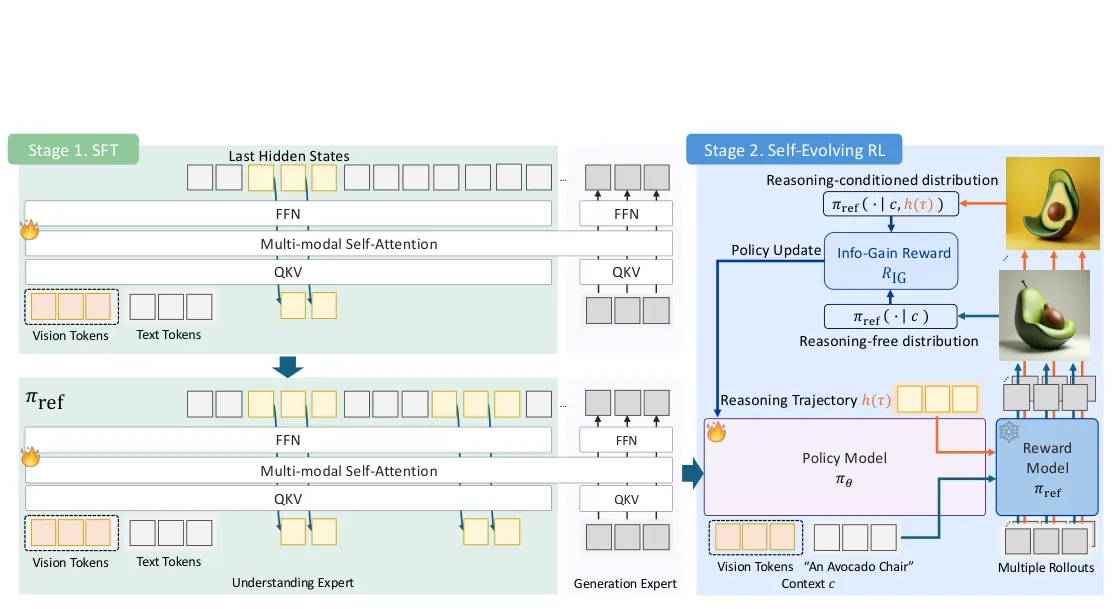
What it is
Moves multimodal reasoning from discrete text tokens into continuous latent states, then trains it with curriculum SFT plus self-rewarded RL to improve image generation and scaling. Instead of token CoT that mismatches continuous image synthesis, reasoning runs in continuous hidden states and is refined with information-gain RL, enabling generation-aware reasoning and test-time scaling.
Key results
- GenEval overall 0.88 vs BAGEL 0.81 and Uni-CoT 0.83
- DPG-Bench overall 90.04 vs BAGEL 85.07
- OneIG-Bench overall 0.866 vs BAGEL 0.764 and Uni-CoT 0.790
Shows that aligning reasoning with the continuous image-generation space unlocks stronger controllability and real test-time scaling in unified multimodal models.