Paper

The Physics of Multi-Turn Long-Horizon Planning: From Pre-training to Post-training via Single- and Multi-Teacher On-Policy Agentic Distillation

A controlled study of long-horizon agent planning that contrasts world-model pre-training, GRPO vs OPD shaping, and multi-teacher OPD integration.

arXiv ↗Jul 27, 2026Code ↗

  • nlp
  • llm
  • agent planning
  • distillation
  • reinforcement learning
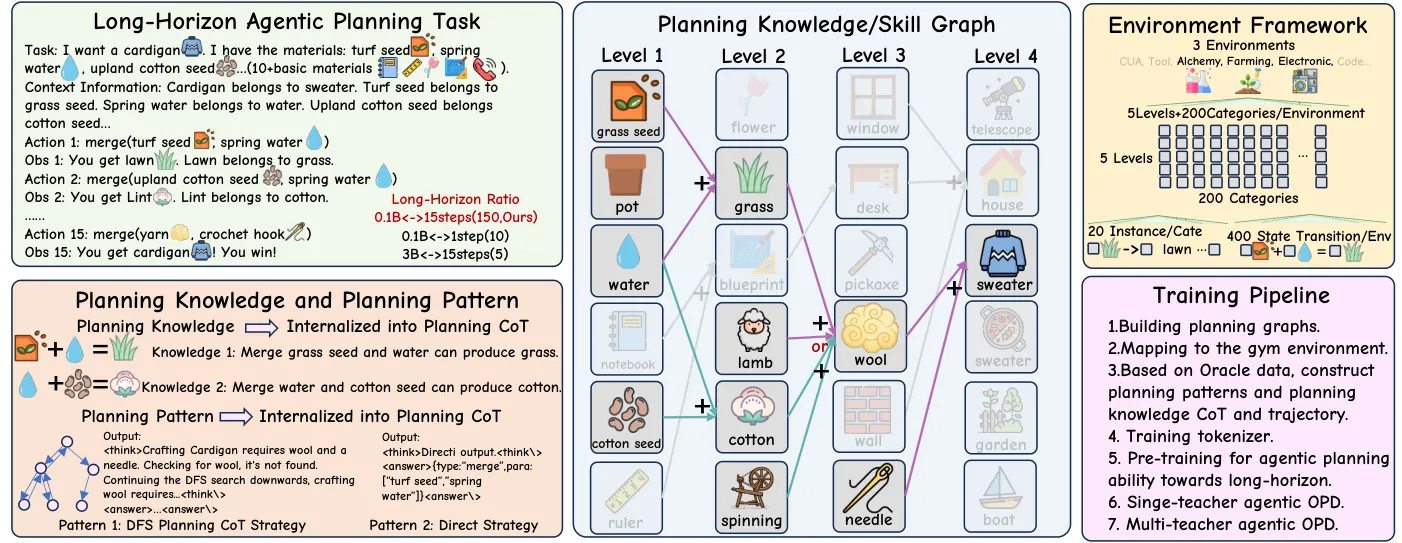
Composite overview of task, knowledge graph, environment, and training pipeline

What it is

Builds a controlled multi-turn planning gym to study how long-horizon planning is learned, improved by post-training, and merged across teachers. Instead of treating planning gains as opaque, it uses a controllable environment to isolate pre-training, RL post-training, and multi-teacher distillation effects. It shows CoT state-transition world modeling and on-policy distillation matter more than atomic skills or GRPO in hard settings.

Key results

  • Long-horizon accuracy 93.1 with world modeling vs 0.3 without
  • Adding 5% long-horizon data raises long-task accuracy from 0.0 to 47.2
  • Suboptimal data drops long-horizon pass@8 from 71.8 to 0.0

Long-horizon planning depends on explicit world-modeling and clean long-horizon supervision, while on-policy distillation is more reliable than RL credit assignment in harder regimes.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.