Paper

InternW0-Δ: A World Action Model Bridging Predictive Dynamics and Actions with 20K+ Hours of Open Data

A directed world-action model that uses predictive video features for control without future rollout at inference, plus training-only 4D distillation.

arXiv ↗Sep 25, 2026

  • robotics
  • cv
  • world models
  • imitation learning
  • robot manipulation
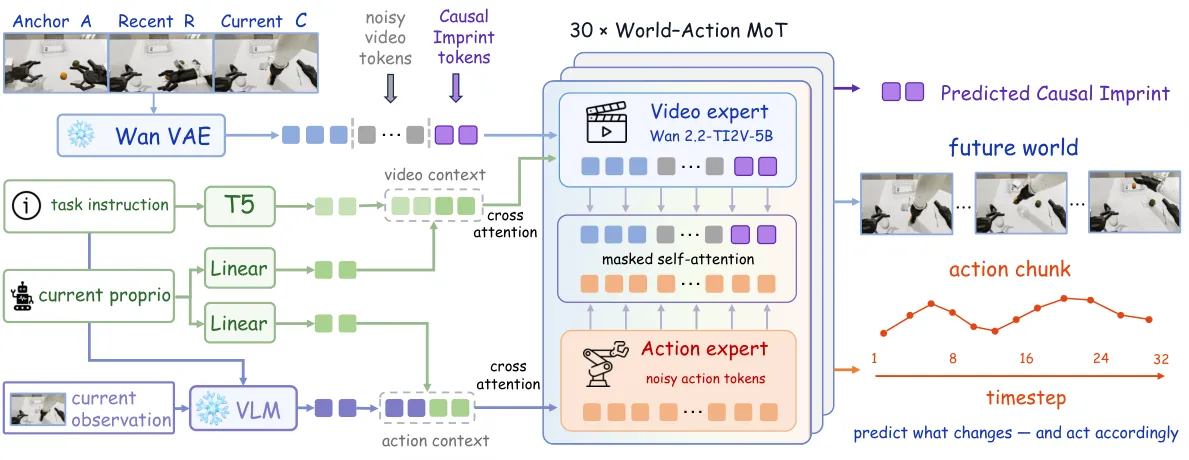
Detailed pipeline diagram showing World-Action MoT architecture with experts and data flow

What it is

A world action model for robot manipulation that fuses video dynamics, VLM semantics, and 4D priors, pretrained on 23K hours of open heterogeneous data. Unlike WAMs that need future-video rollout or weaker visual priors, it couples a pretrained video expert and action expert in a directed MoT. Causal Imprint turns future supervision into action-relevant predictive features, while 4D priors are added by training-only distillation.

Key results

  • 92.8% on LIBERO-Plus, best under distribution shift
  • 71.9% on RoboTwin 2.0 Clean2Random; 90.0% on Clean2Clean
  • 23.9% on RoboDojo, nearly 2x the strongest prior WAM

Predictive video supervision helps robot control most when converted into action-facing features rather than requiring test-time future generation.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.