Paper

ClinFusion: A Vision-Centric Multimodal LLM System for Holistic Medical Understanding

Replaces monolithic medical vision encoders with cascaded 2D+3D fusion, then evaluates with MedIF-Bench and RoI-grounded report scoring.

arXiv ↗Jul 27, 2026Code ↗

  • cv
  • llm
  • nlp
  • multimodal
  • medical vision-language
  • 3d imaging
  • report generation
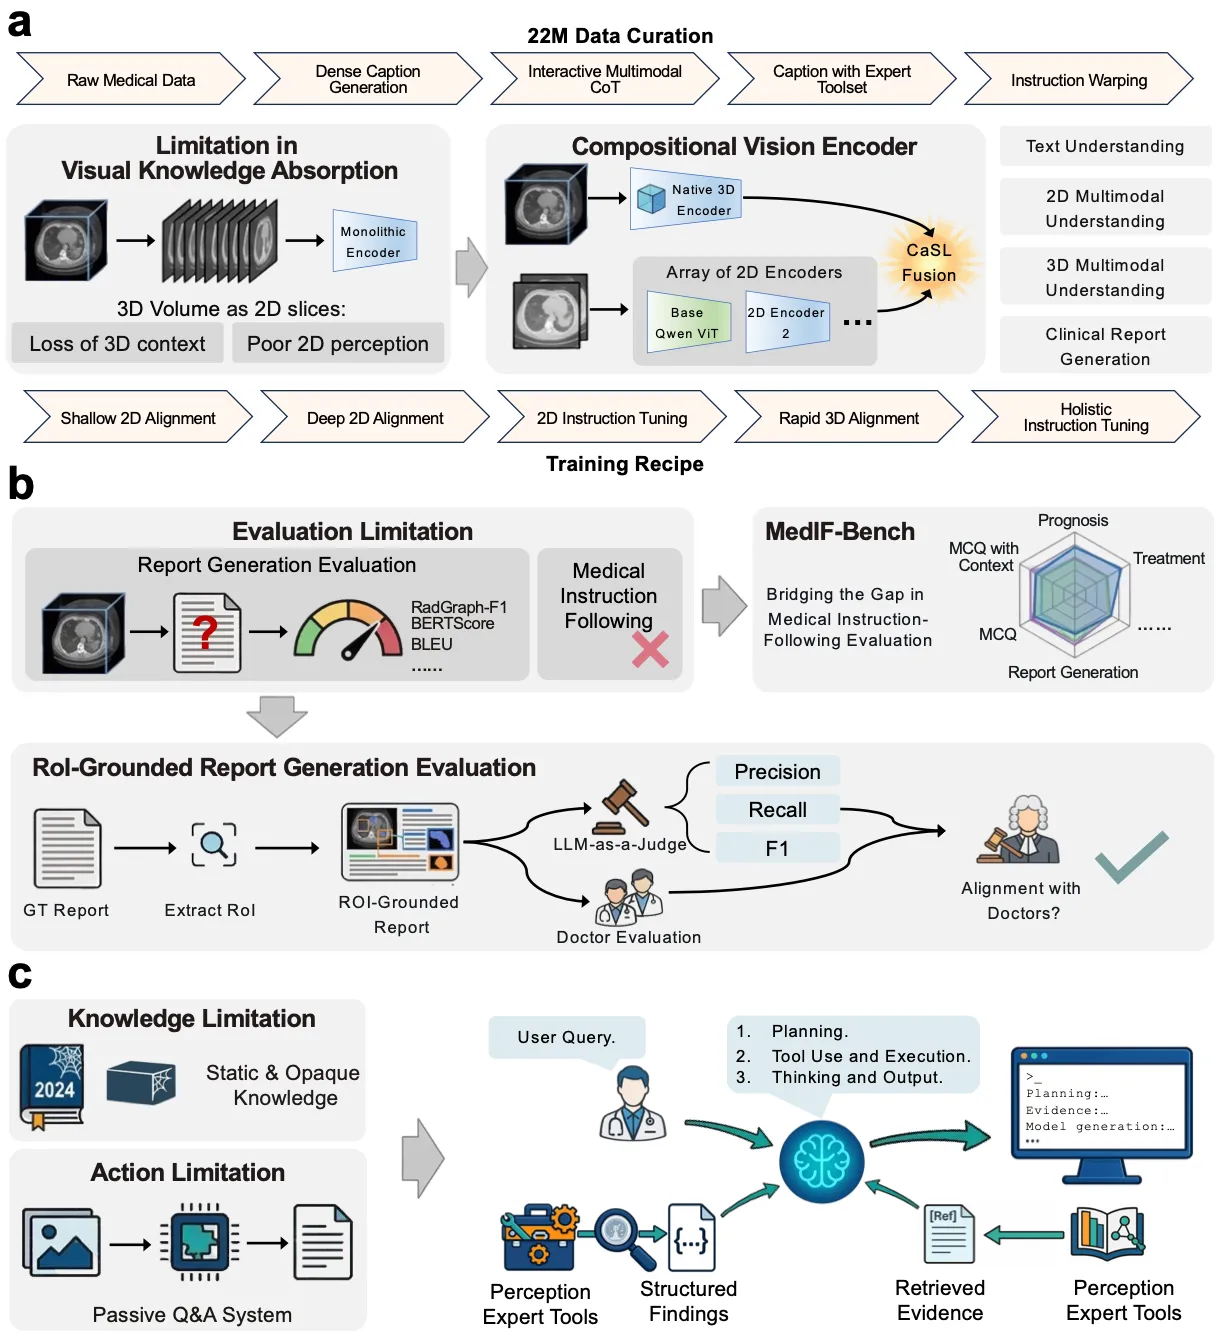
Comprehensive pipeline diagram showing data curation, vision encoder, evaluation, and agent framework

What it is

Vision-centric medical MLLM that fuses specialist 2D encoders with a native 3D encoder, and adds clinically grounded evaluation for instruction following and report generation. Instead of a single 2D-centric vision tower, it composes specialist 2D encoders with a native 3D encoder via cascaded, 2D-anchored fusion, and evaluates with instruction-following plus RoI-grounded report scoring.

Key results

  • Beats open-source medical MLLMs on 20 of 24 benchmarks
  • Beats GPT-5.2 and Gemini-3-Flash on 13 of 16 multimodal benchmarks
  • MedIF-Bench Overall-IF: 98.9, above GPT-5.2 96.0 and Gemini-3-Flash 96.6

Medical MLLMs benefit from native 3D-aware, multi-encoder vision design and clinically grounded evaluation rather than a single generic vision tower.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.