Paper

Youtu-Parsing-Omni: One Encoder, One Schema, All Modalities

Replaces separate modality towers and task formats with one shared encoder and one grounded JSON schema across documents, images, audio, and video.

arXiv ↗Oct 29, 2026Code ↗

  • cv
  • multimodal
  • document parsing
  • audio-video understanding
  • multitask learning
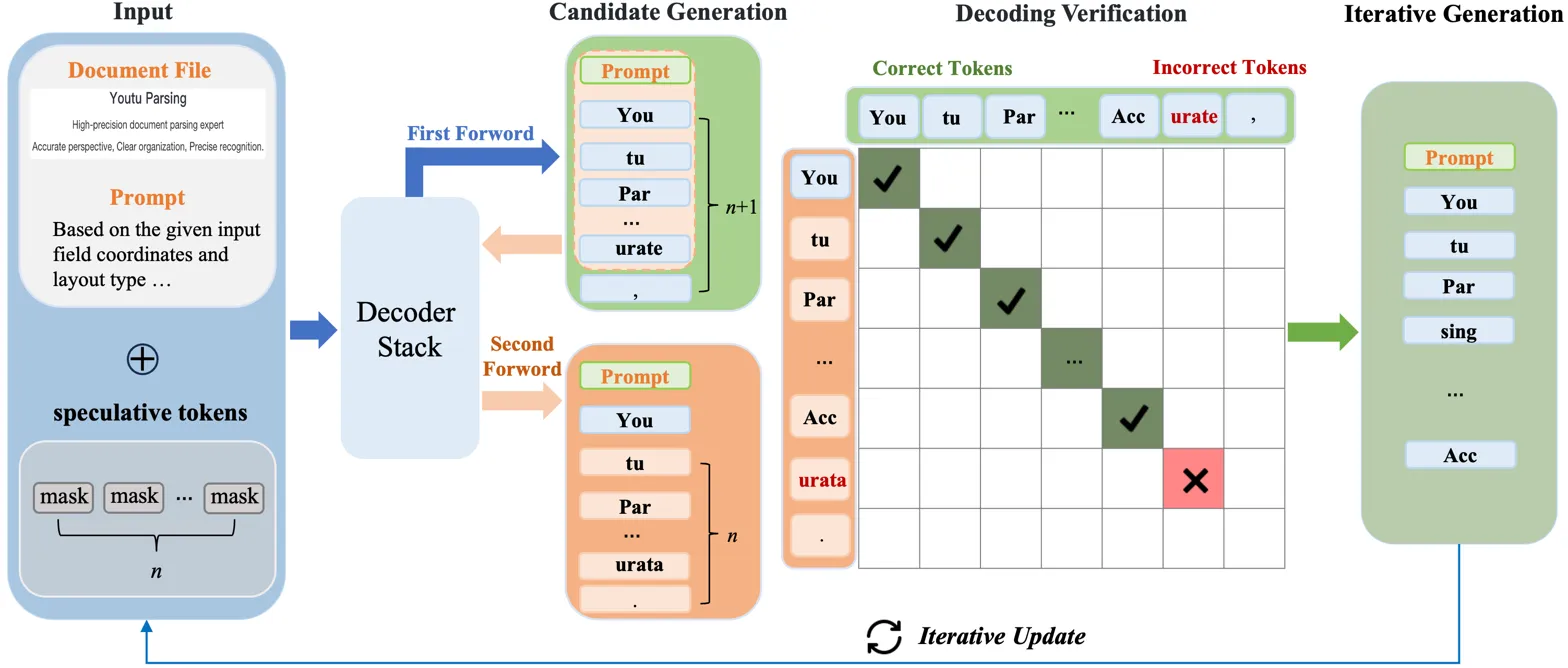
Pipeline diagram showing speculative decoding method with verification and iterative generation

What it is

A single 5B parser turns documents, images, audio, and video into one grounded JSON schema using a shared encoder and shared post-training objective. Instead of separate vision/audio towers and task-specific outputs, it uses one shared encoder with unified space-time positions plus one schema for 10 parsing tasks; training is unified by self-distilled on-policy token supervision rather than hand-designed rewards.

Key results

  • 96.96 on OmniDocBench v1.6, ahead of TeleOCR at 96.91
  • 75.08 on OmniParsingBench, beating Logics-Parsing-Omni's 72.26
  • 54.2 [email protected] on chemistry vs DeepSeek-OCR 2 at 49.6

A mostly shared encoder plus a unified output schema can cover broad multimodal parsing without giving up specialist-level precision.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.