
What it is
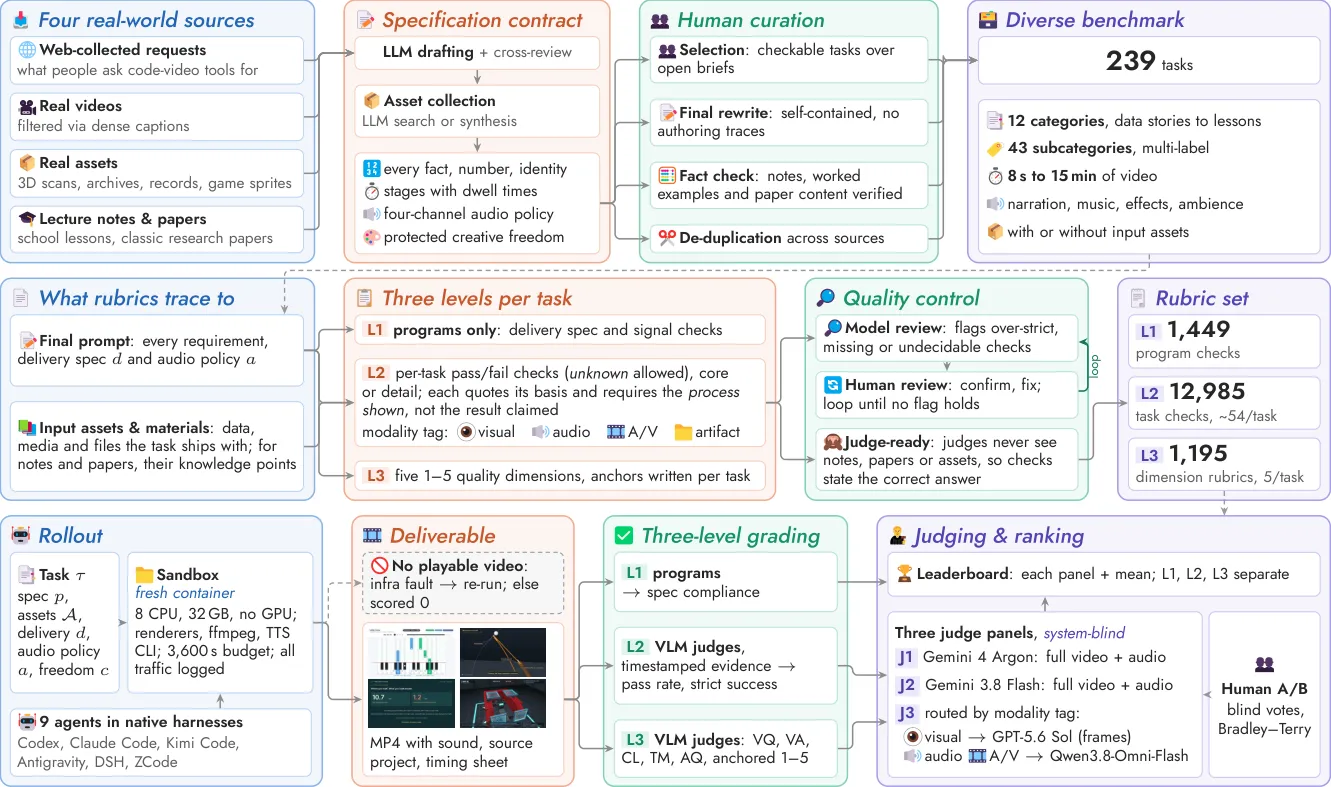
A benchmark for testing multimodal agents that generate full videos by writing code, not pixels, with evidence-based grading over 239 tasks. Targets code-rendered audiovisual videos rather than diffusion clips or single-call code artifacts: agents must autonomously build an MP4 in a 1-hour sandbox, scored by program checks, task-specific rubrics, and VLM judges.
Key results
- Best strict success: 76.3% of tasks by Claude Opus 5.5
- GPT-6 Astra ranked #1 on delivered-video L3 overall with 4.126
- Judge system ranking matched human preferences with ρ=0.98
For code-driven video agents, planning and delivery reliability are as important as raw content quality.