Paper

Robostral Navigate

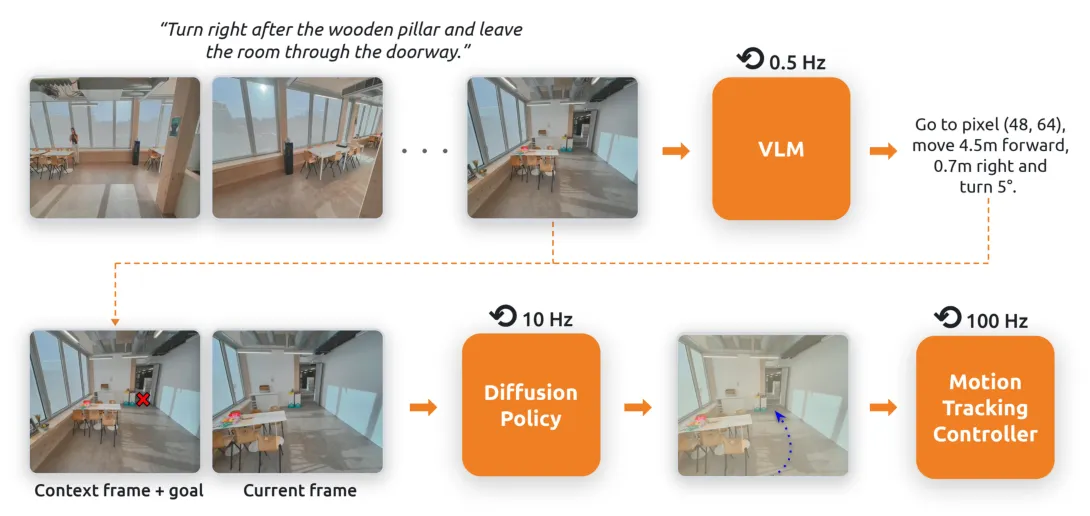
A monocular RGB navigation policy that predicts image-space waypoints instead of robot-frame actions, then uses a small diffusion policy to turn them into motion.

arXiv ↗Jul 22, 2026

  • robotics
  • llm
  • embodied navigation
  • vision-language models
  • reinforcement learning
Pipeline diagram showing VLM, diffusion policy, and motion controller with data flow

What it is

An 8B VLM for language-guided robot navigation that uses only monocular RGB, predicts image-space waypoints, and trains efficiently from large-scale simulation. Instead of depth, multi-camera, or robot-specific coordinates, it navigates by pointing to the next waypoint in image space from monocular RGB, with displacement fallback, plus prefix-tree training and RL for recovery.

Key results

  • R2R-CE: 77.4% SR, +10.5 pts over best monocular baseline
  • R2R-CE: beats best depth/multi-camera system by 5.3 SR points
  • RxR-CE: 75.1% SR, 68.7% SPL; RL adds +3.9 SR over SFT

Shows that image-space waypoint prediction plus efficient sim-first training can beat privileged-sensor navigation systems.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.