Paper

Stale but Stable: Staleness-Adaptive Trust Regions for Stabilizing Asynchronous Reinforcement Learning

A staleness-aware PPO variant that contracts only the risky side of the clip interval for high-mismatch samples, leaving normal updates unchanged.

arXiv ↗Jul 21, 2026Code ↗

  • rl
  • policy optimization
  • asynchronous rl
  • ppo
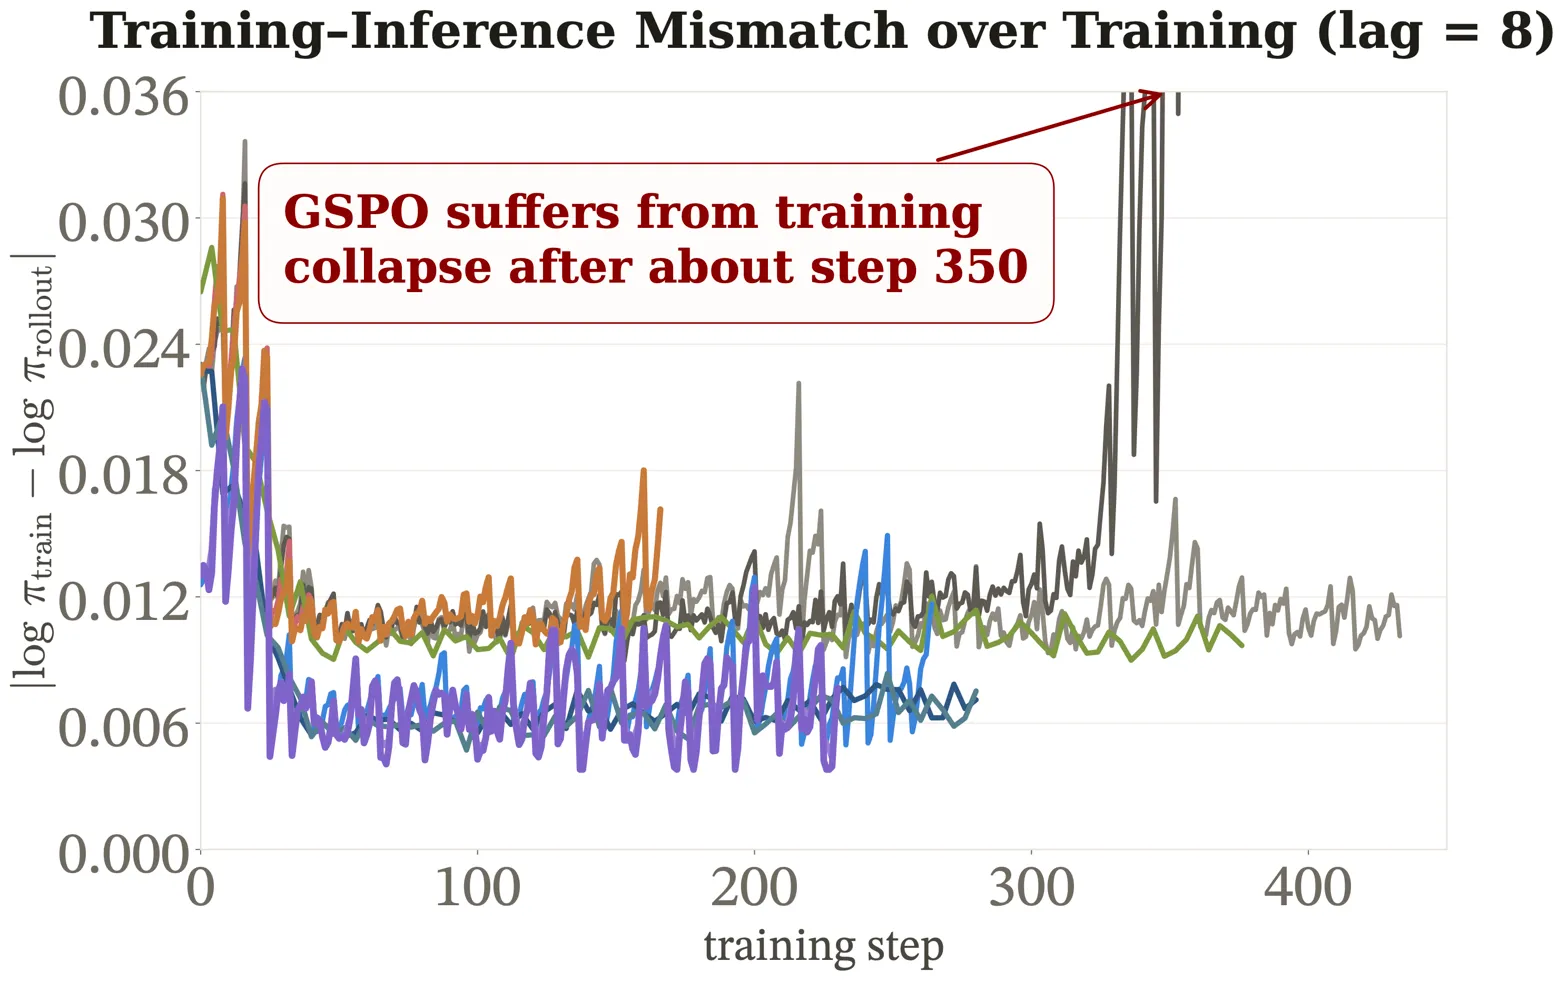
Shows core claim: GSPO training collapse, key comparative finding of the work

What it is

Adapts PPO clipping to rollout staleness in asynchronous RL, tightening only high-mismatch updates to stabilize training under policy lag and engine mismatch. Instead of PPO's fixed clip for all tokens, SAT shrinks only the outward clip boundary on high-staleness samples, using detached log-ratio as a staleness proxy; ordinary and pull-back updates stay unchanged.

Key results

  • 35.83 AIME24 avg@8 at lag 1 with SAT-GSPO w/ R3
  • 34.79 AIME24 avg@8 at lag 8 with SAT-GSPO w/ R3
  • 34.17 AIME24 avg@8 at lag 1 with SAT-GSPO

Shows that matching trust-region strength to per-sample staleness can stabilize asynchronous RL without globally shrinking all updates.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.