Paper

Parallel Decoding Distillation for Fast Image and Video Generation

A trajectory distillation method that predicts multiple denoising steps at once, replacing VSD/GAN-based few-step training with simple regression.

arXiv ↗Jul 28, 2026Code ↗

  • cv
  • llm
  • multimodal
  • diffusion models
  • video generation
  • distillation
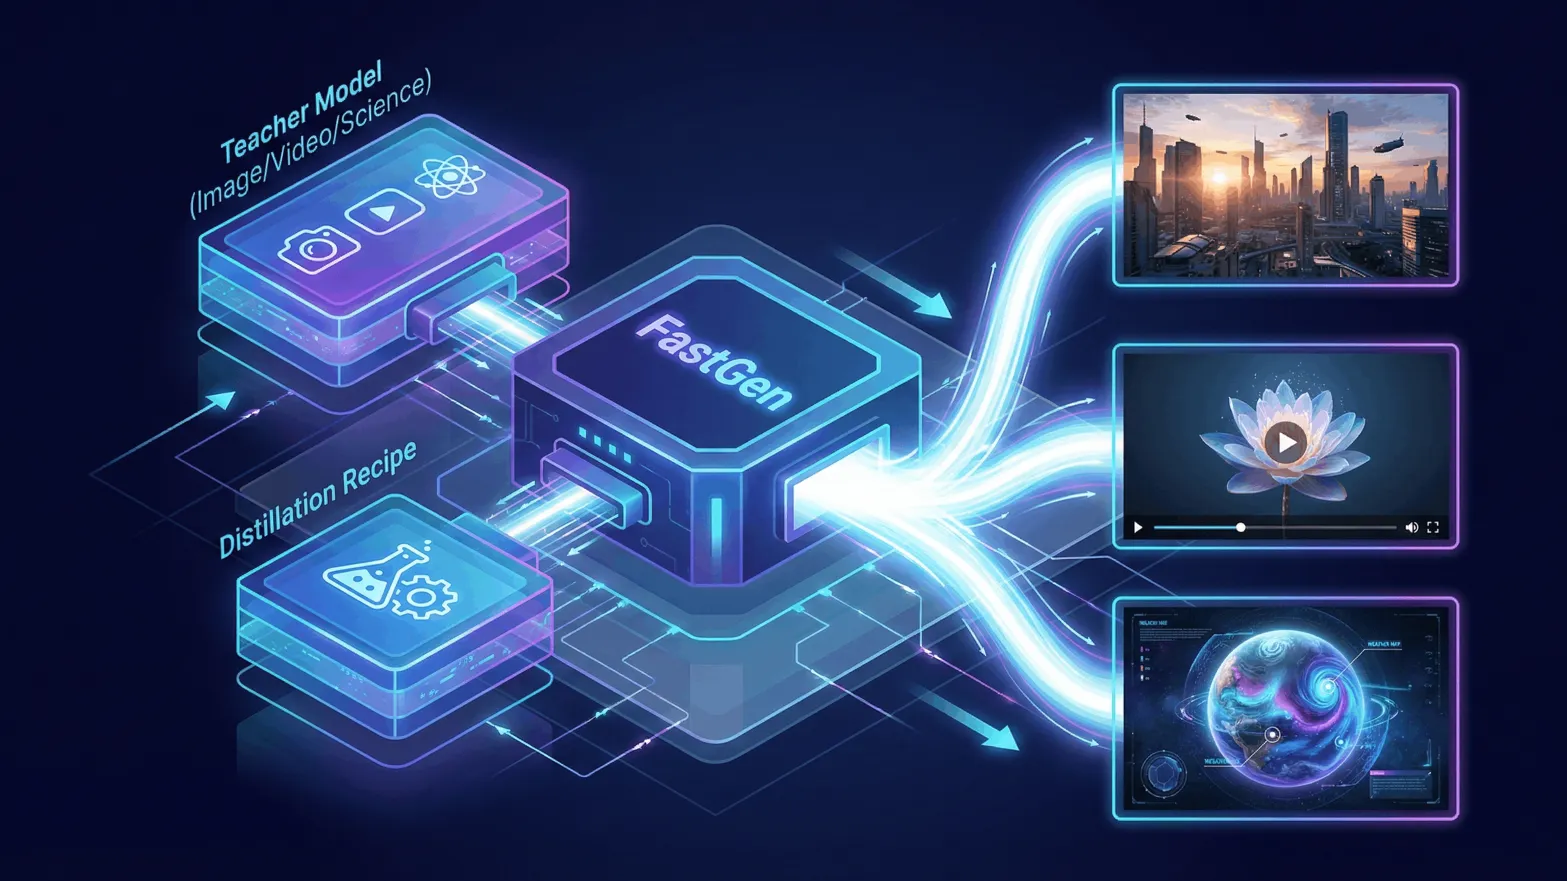
Stylized pipeline diagram showing FastGen distillation from teacher model to outputs

What it is

Distills diffusion and flow models into 4-8 step image/video generators by predicting multiple denoising steps per network call, improving speed and video diversity. Instead of VSD/GAN distillation or collapsing steps into one big update, it predicts several teacher trajectory steps in parallel per eval. It distills mean velocities with a simple regression loss, no JVPs, finite differences, or extra policy head, and supports variable NFE.

Key results

  • SOTA with 4-8 NFE on LTX-2.3 T2V/audio, Wan 14B T2V, and Qwen-Image
  • SOTA video quality at 4 NFE on Wan2.1 1.3B/14B using VBench
  • Improves video diversity over DMD2, AnyFlow, and official distilled baselines

Few-step generation can match top quality without adversarial or VSD losses if the student learns parallel mean-velocity segments of the teacher trajectory.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.