Paper

Kimi K3: Open Frontier Intelligence

A jointly scaled pretrain+RL recipe for an open 2.8T multimodal MoE, using 1M-context architecture and multi-effort agentic/coding training.

arXiv ↗Jul 27, 2026Code ↗

  • nlp
  • llm
  • mixture-of-experts
  • long-context
  • agentic reasoning
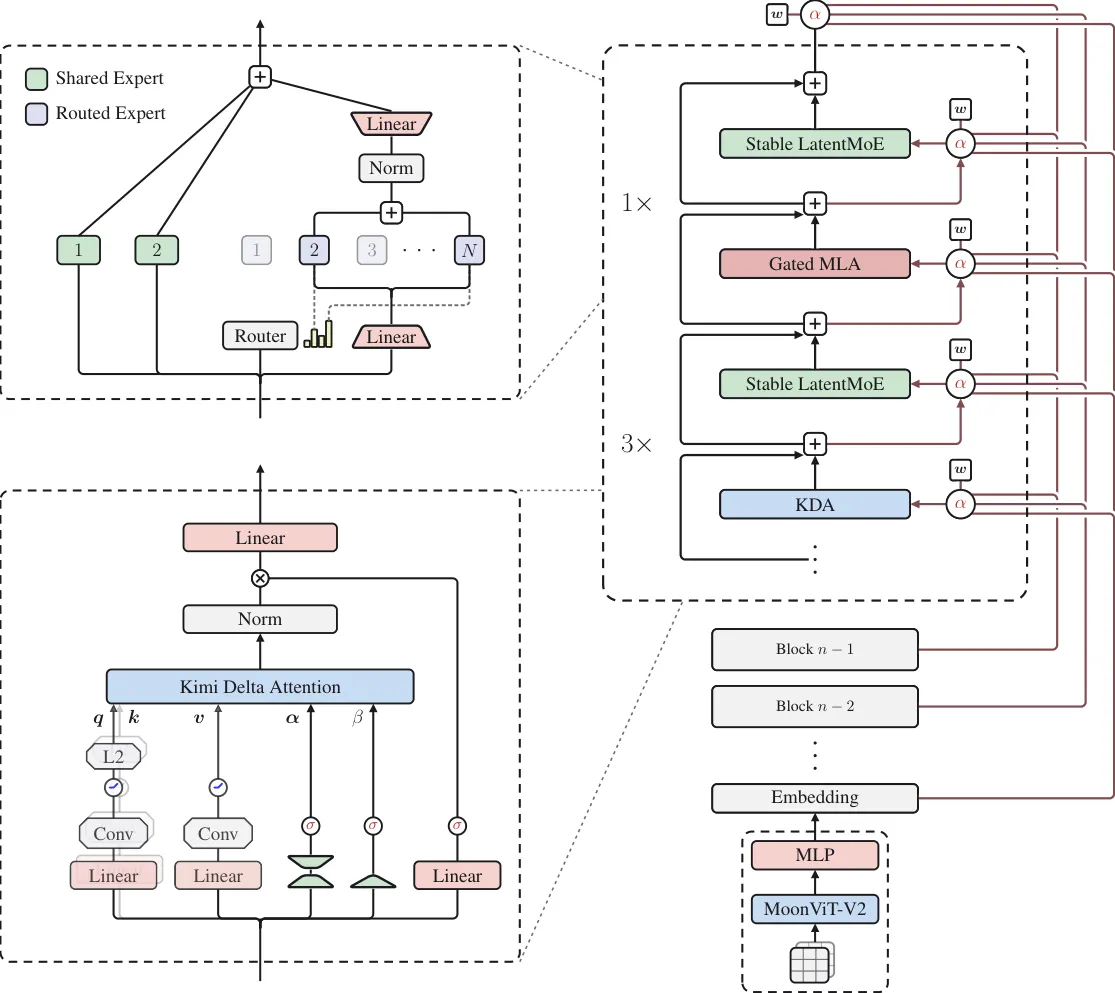
Detailed model architecture diagram showing MoE, attention, and pipeline components

What it is

A 2.8T-parameter open multimodal MoE with 104B active params, 1M context, and RL for coding, agents, reasoning, and vision. Instead of only scaling post-training on ~1T-class open models, it jointly scales pretraining and test-time RL: a 2.8T MoE with long-context KDA, depth-wise attention residuals, sparse 896-expert routing, then multi-effort agentic/coding RL distilled into one model.

Key results

  • ProgramBench: 76.9, above GPT-5.6 Sol 72.9 and Fable 5 71.7
  • AutomationBench: 30.8, above GPT-5.6 Sol 29.7 and Fable 5 29.1
  • SWE-Marathon: 46.0, above Opus 4.8 41.0 and GPT-5.6 Sol 35.0

Shows open models can reach near-frontier agentic and coding performance by scaling both the base model and long-horizon RL together.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.