Paper

Library of Layers (LoL): Adaptively Ordering Transformer Layers at Runtime

A router selects the next block from a shared layer library at each depth, so execution order changes per input instead of staying fixed.

arXiv ↗Nov 2, 2026Code ↗

  • llm
  • nlp
  • transformers
  • mixture of experts
  • dynamic routing
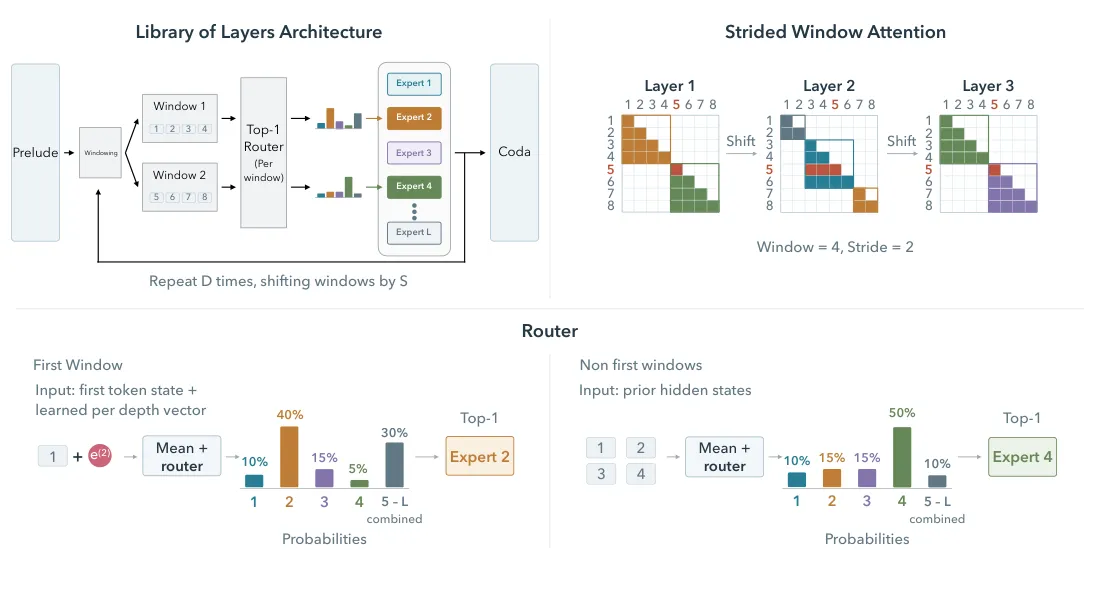
Detailed method diagram showing layer architecture, strided attention, and router mechanism

What it is

A transformer that chooses and reorders its layers at inference time, letting one model span dense, recurrent, and sparse expert regimes with input-dependent execution paths. Instead of fixed-depth order or routing only within a layer, a router picks the next transformer block from a global library at each depth. This makes layer order, reuse, and sparsity input-dependent, unifying dense, looped, and MoE-style models.

Key results

  • Safety probe on sequence-level routing features reaches 0.95 AUROC
  • Maze strategy control hits 99.79-100% correct forced-strategy traces
  • Sudoku forced routing yields 99.5-100% requested-strategy accuracy

Shows that layer order can be a learned, controllable part of transformer computation rather than a fixed architectural choice.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.