Paper

RynnWorld-Teleop: An Action-Conditioned World Model for Digital Teleoperation

A robot-centric action-conditioned world model that replaces physical teleop with real-time video generation from hand poses and a single scene image.

arXiv ↗Jul 7, 2026Code ↗

  • robotics
  • world models
  • imitation learning
  • sim2real
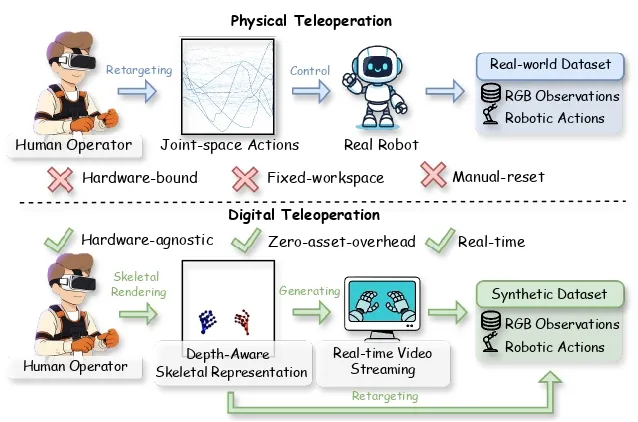
Pipeline comparing physical vs digital teleoperation, showing the method's core contribution

What it is

Introduces digital teleoperation: a robot-centric world model that turns hand-pose streams plus one reference image into real-time egocentric robot videos and action-labeled training data. Instead of physical teleop or passive human-to-robot video translation, it generates robot-egocentric videos directly from hand poses, with actions preserved for retargeting. It combines depth-aware skeletal control, human-to-robot pretraining, and distilled streaming inference for real-time use.

Key results

  • 40+ FPS real-time generation on a single H100 GPU
  • Policies trained only on generated data achieve zero-shot Sim2Real transfer
  • Adding digital-teleop data consistently improves real-world success rates

Shows robot training trajectories can be generated interactively by a world model and still transfer to real robots without physical teleoperation.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.