Repo

lingbot-vision

Loads self-supervised ViT backbones that produce dense patch tokens with boundary-aware spatial structure. Includes pretrained weights, token extraction, and PCA visualization.

GitHub ↗Jul 6, 2026

  • cv
  • self-supervised
  • vision-transformer
  • dense-prediction
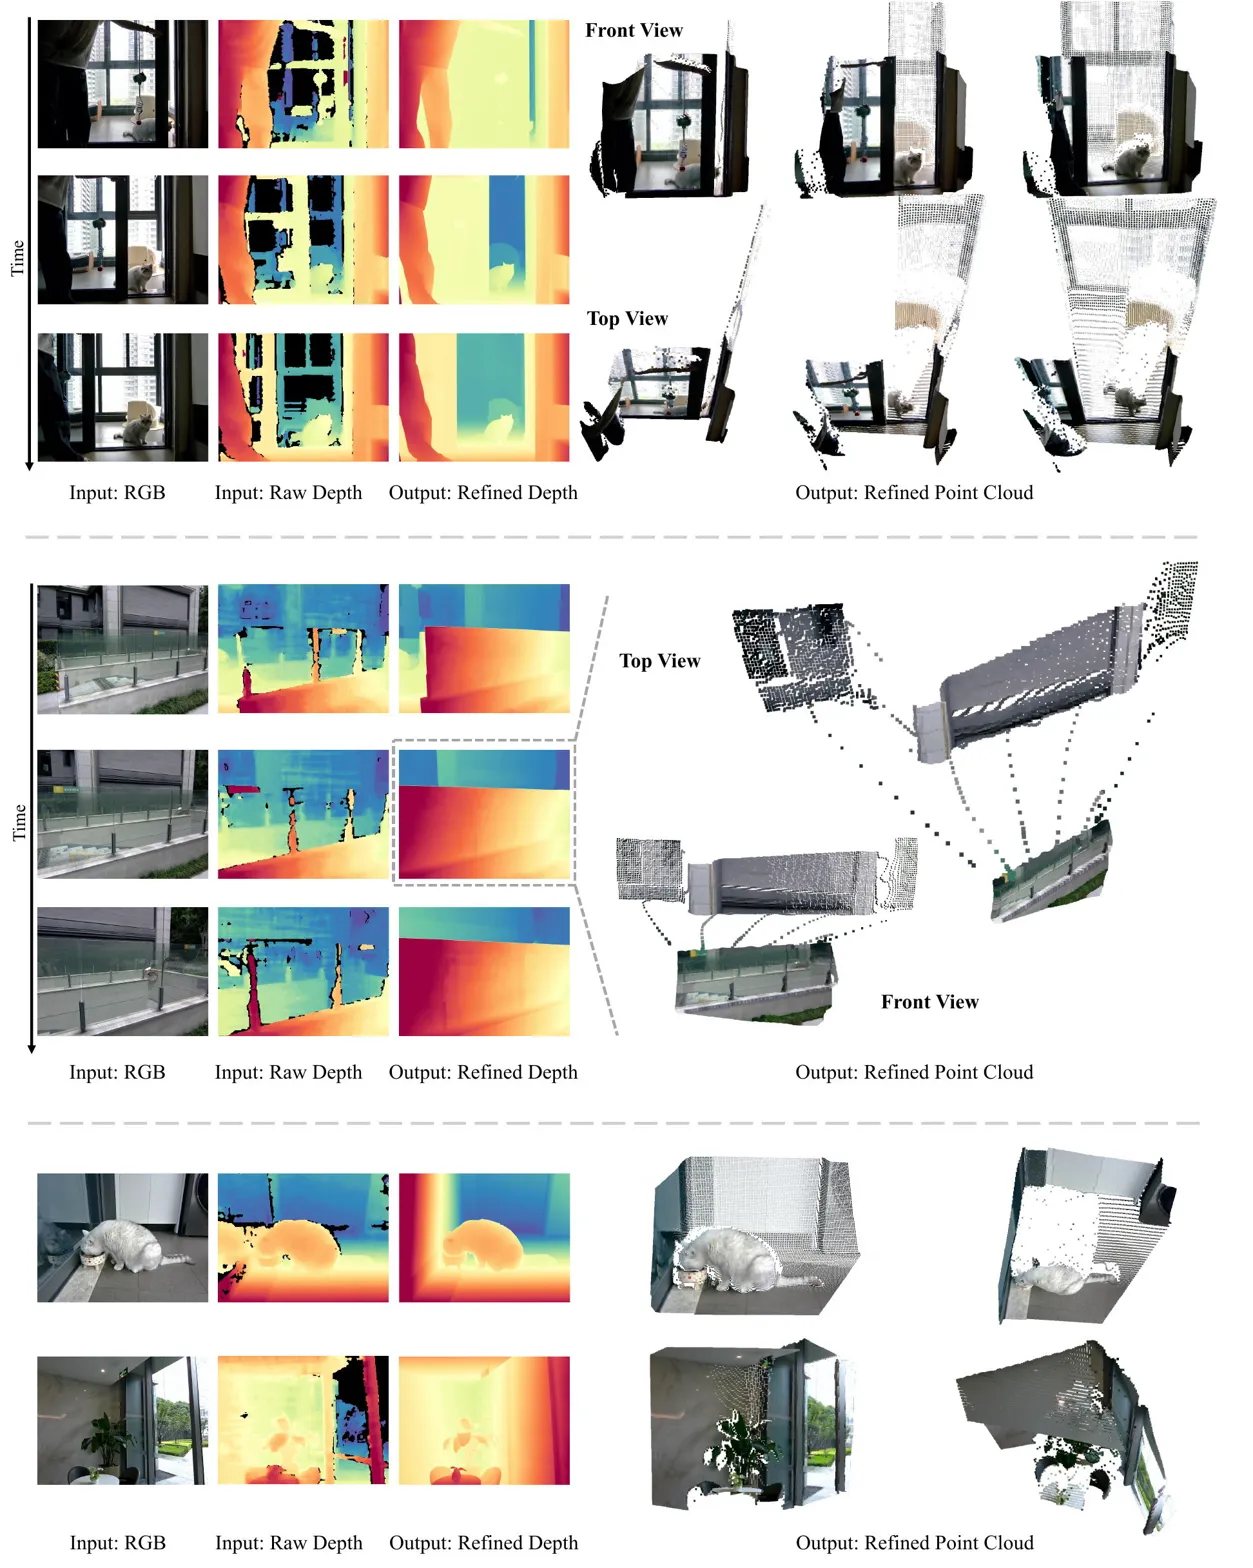
Composite showing RGB, raw/refined depth, and point cloud outputs across scenes

What it is

Self-supervised ViT backbones pretrained for dense spatial perception, exposing patch features that preserve boundaries, shapes, and semantic regions. Provides pretrained ViT visual encoders for extracting dense patch tokens that align with object boundaries and spatial structure, with loaders and PCA demos for downstream depth, segmentation, and token matching.

Key results

  • Released backbones span ViT-S/16 to 1.1B-parameter ViT-g/16
  • Extracts patch tokens as [B, H*W, C]; example: [1, 1024, 384] at 512 px
  • Backbone-only .pt checkpoints auto-download from Hugging Face

Shows self-supervised ViT pretraining can produce frozen features that capture geometry and semantics together for dense perception.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.