
What it is
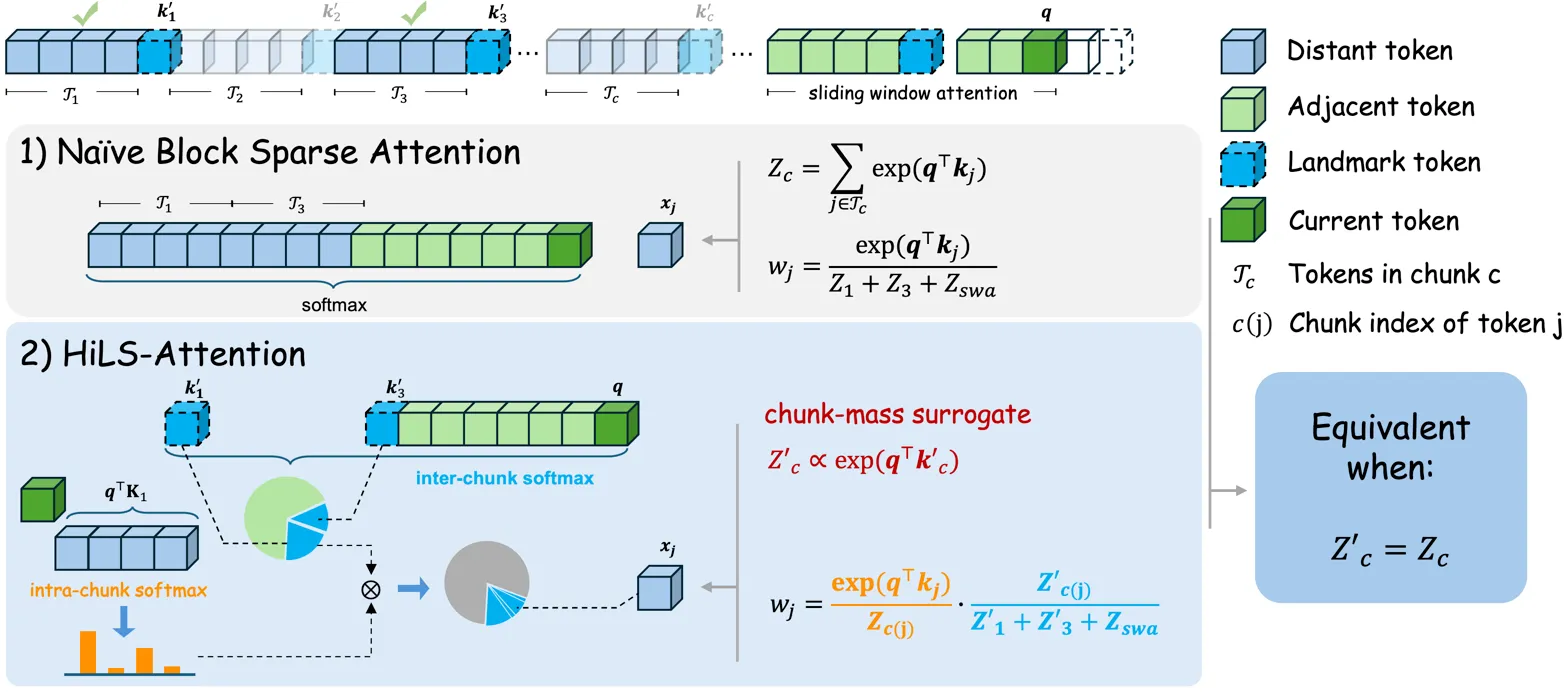
A sparse LLM attention that learns chunk retrieval under LM loss, matching full attention in-domain while extrapolating to ultra-long contexts with faster inference. Unlike prior chunk-wise sparse attention with fixed or weak chunk scoring, HiLS puts retrieval scores into the forward attention so chunk selection is learned end-to-end. It uses hierarchical chunk-then-token attention with learned landmark summaries for native sparse training.
Key results
- 90.7% RULER EM at 256K after 8K training; full-attn YaRN baseline collapses
- 9.3x faster prefill and 15.7x faster decode than full attention at 512K
- After 50B continued training, LongBench >8K overall 33.6 vs 32.9 for full attention
End-to-end learned sparse retrieval can beat full attention on long-context use while also improving efficiency and length extrapolation.