
What it is
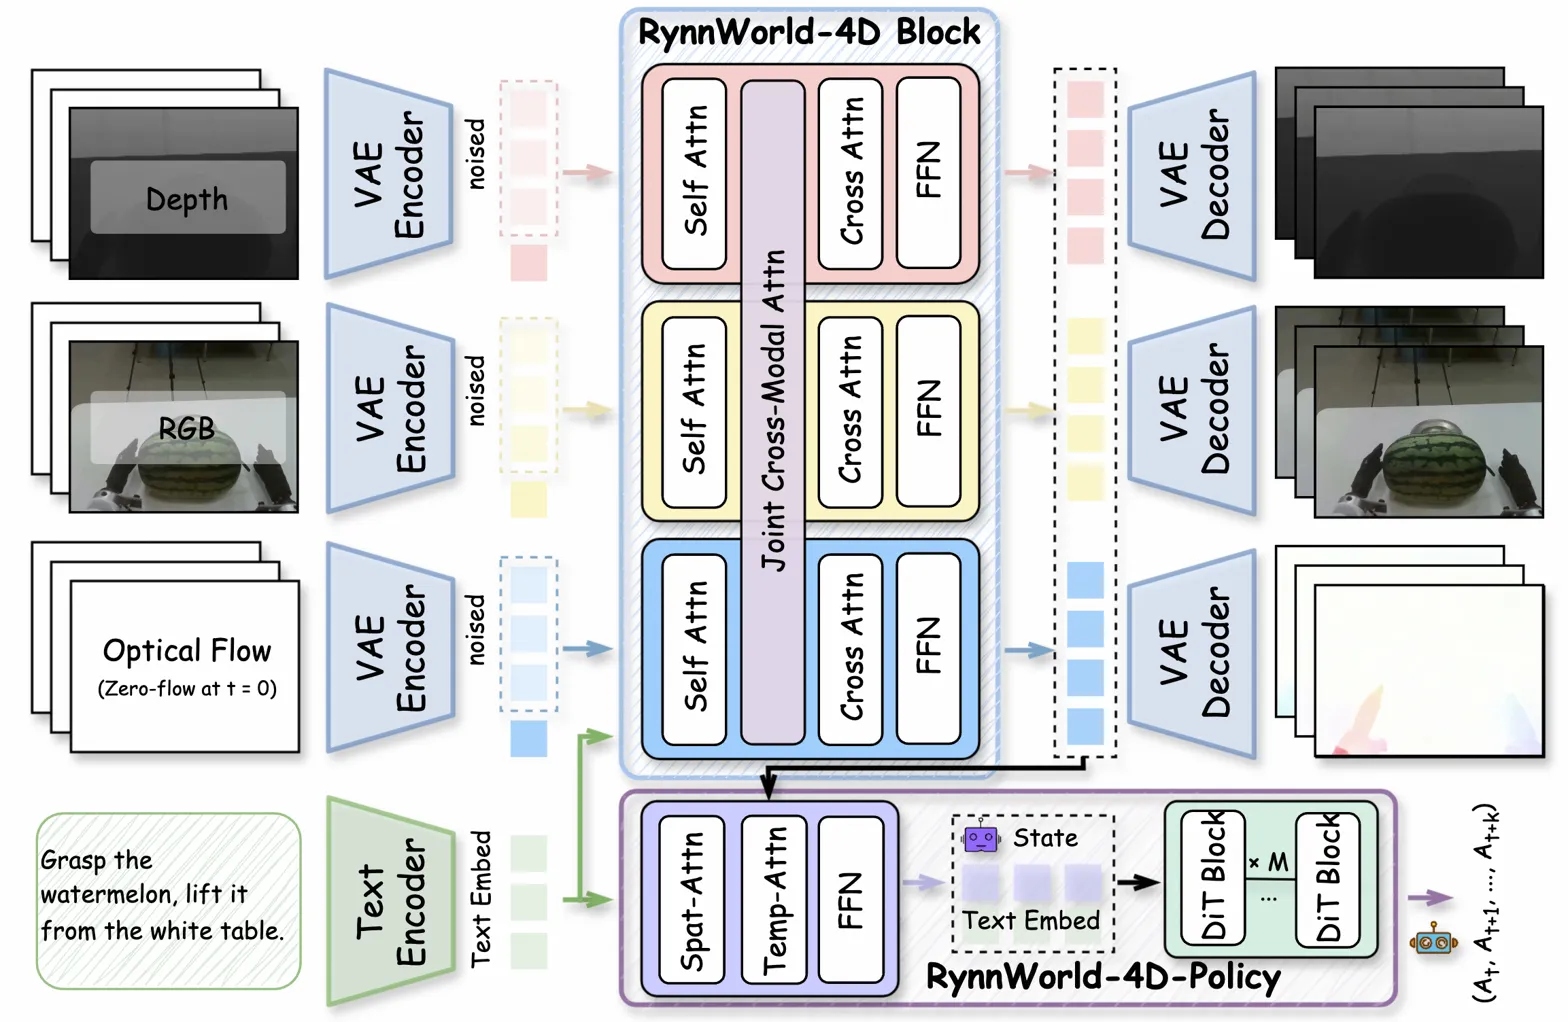
A 4D robotic world model that jointly predicts RGB, depth, and optical flow from one RGB-D view plus language, then reuses its internal features for closed-loop action prediction. Instead of RGB-only video world models or heavy 3D scene models, it predicts synchronized RGB-depth-flow in one diffusion model, making 3D motion explicit and feeding those 4D latents to a single-pass inverse-dynamics policy.
Key results
- Rynn4DDataset 1.0 contains 254.4M+ frames for 4D world-model training
- Generates temporally and spatially coherent RGB-depth-flow predictions
- Achieves SOTA on real-world dexterous bimanual manipulation tasks
Explicit geometry and motion in projective 4D latents make world-model features more directly usable for precise closed-loop manipulation.