Paper

Mage-VL: An Efficient Codec-Native Streaming Multimodal Foundation Model

Codec-native sparse video tokens replace dense sampled frames, then an event gate activates the decoder only when needed for streaming interaction.

arXiv ↗Jul 27, 2026Code ↗

  • cv
  • nlp
  • multimodal
  • video understanding
  • streaming
  • vision-language models
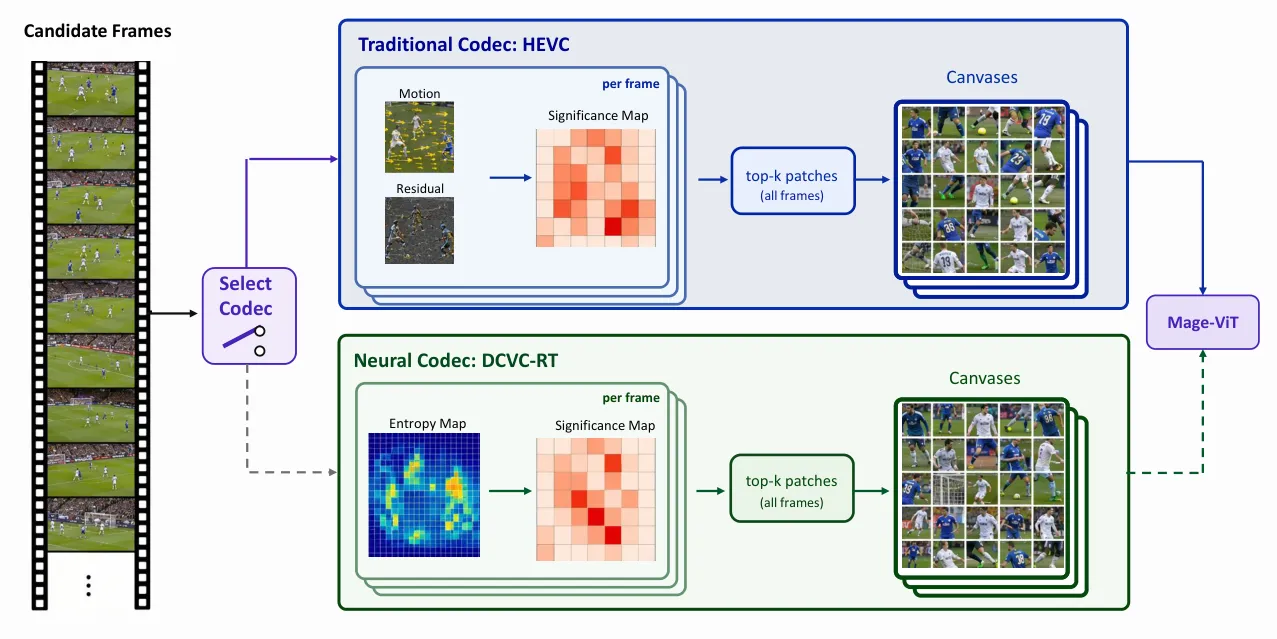
Pipeline diagram showing codec selection, significance maps, patch selection, and Mage-ViT flow

What it is

A codec-native streaming VLM that encodes only motion-salient video patches and adds an event gate for real-time multimodal interaction. Instead of dense frame sampling then compressing, it tokenizes video in the codec domain: full I-frames plus motion/residual-selected P-frame patches, then uses a lightweight gate to trigger the decoder only on events.

Key results

  • Up to 3.5x wall-clock inference speedup vs uniform frame sampling
  • Over 75% fewer visual tokens while preserving spatiotemporal context
  • Mage-VL-4B matches Qwen3-VL-4B on static tasks and surpasses Phi-4-reasoning-vision-15B

Shows that pushing temporal redundancy removal into the visual tokenizer can improve streaming VLM efficiency without sacrificing broad multimodal capability.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.