Paper

TabFM: A Zero-Shot Foundation Model for Tabular Data

A synthetic-data-trained in-context transformer replaces per-dataset tabular training with single-pass zero-shot prediction on real tables.

arXiv ↗Sep 29, 2026Code ↗

  • llm
  • tabular
  • in-context learning
  • foundation models
  • synthetic data
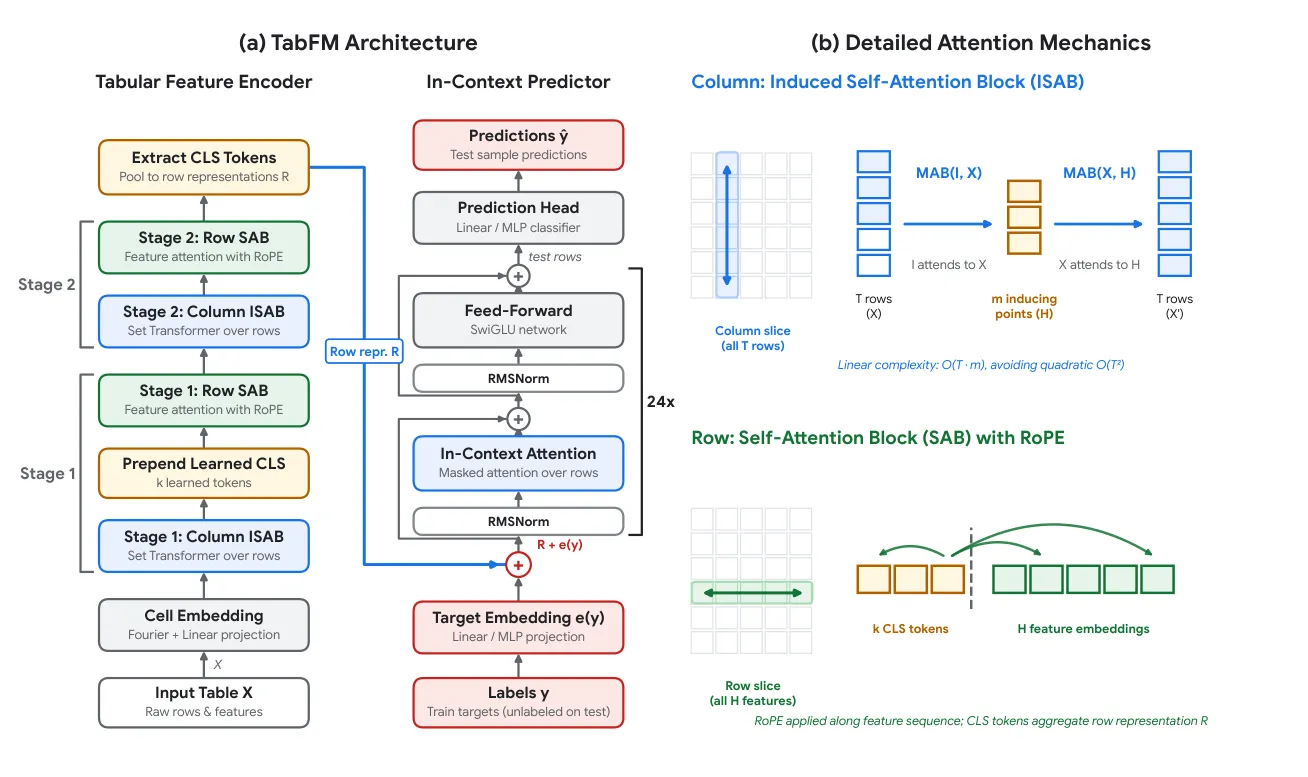
Detailed TabFM architecture and attention mechanics diagram showing the method

What it is

A 400M tabular foundation model does zero-shot supervised prediction as in-context learning, trained only on synthetic SCM tables and run in one forward pass. Instead of fitting trees or AutoML per dataset, it treats tabular prediction as in-context inference: a synthetic-data-trained transformer makes calibrated zero-shot predictions on real tables, with frozen-weight upgrades via ensembling/calibration or LLM-guided feature engineering.

Key results

  • Overall TabArena: 1785 Elo, above AutoGluon 1.5 extreme at 1676
  • Classification: 1768.6 Elo vs TabPFN-3 1641.9 and AutoGluon 1669.7
  • Regression: 2055.2 Elo vs EXAONE-Tabular 1973.1 and TabPFN-3 1866.6

Shows that large tabular models trained purely on synthetic causal tables can transfer zero-shot to real-world datasets at or above tuned AutoML.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.