Paper

YuE2: Unifying Symbolic and Audio Music Generation at Frontier Quality

A unified score-to-audio generator that writes melody/chords first, then renders full-song audio; unlike pure audio models, composition stays explicit and editable.

arXiv ↗Sep 27, 2026Code ↗Dataset ↗

  • audio
  • llm
  • music generation
  • audio generation
  • sequence modeling
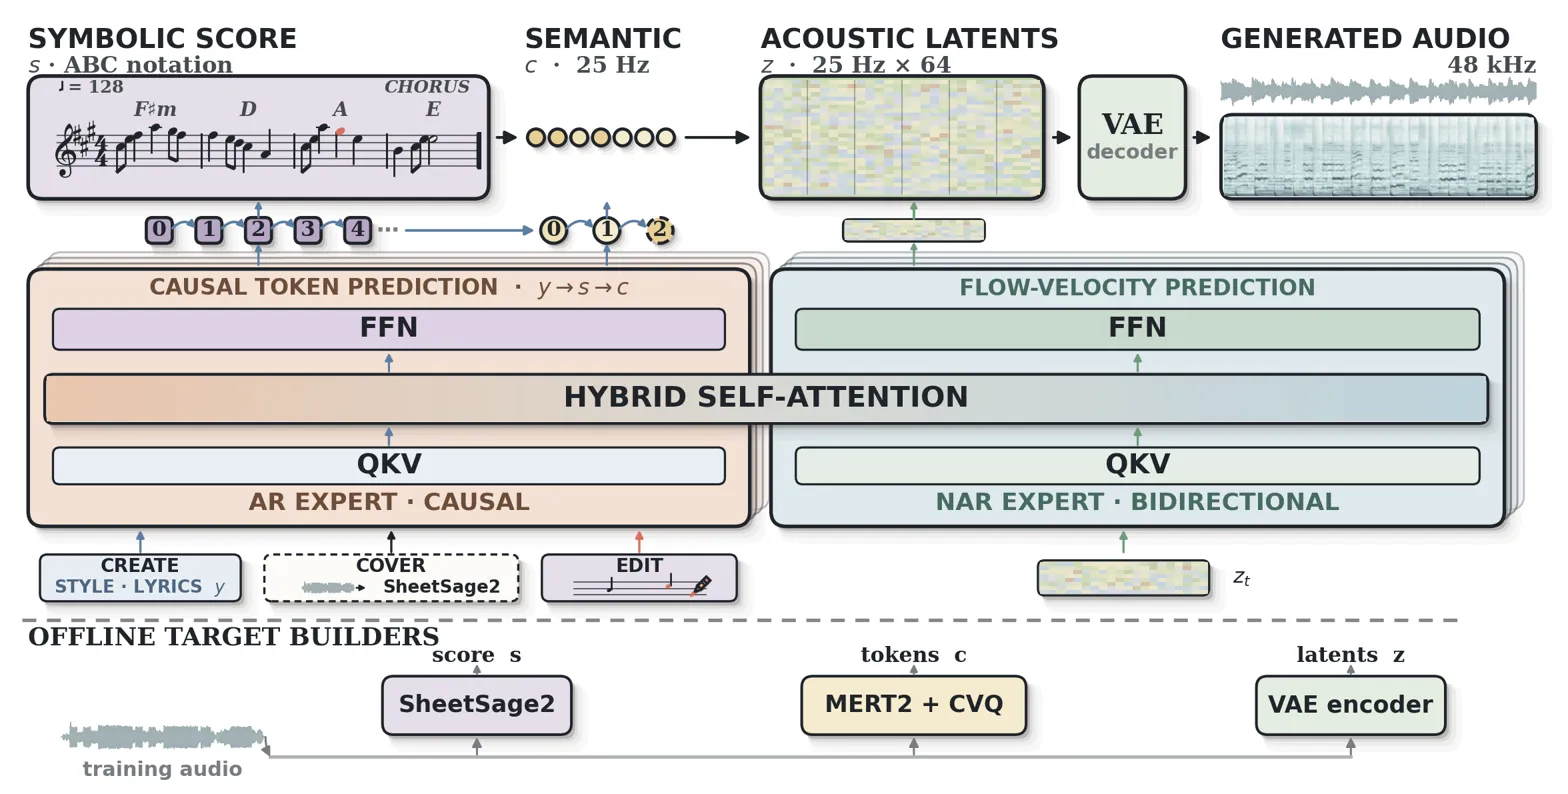
Complete pipeline diagram showing score-to-audio generation architecture with dual experts.

What it is

A single music model plans an explicit symbolic score, then renders semantic tokens and full-song audio. It unifies composition, editing, covers, and audio generation in one checkpoint. Instead of generating audio with composition left implicit, it plans a readable score first, then renders it to semantic tokens and audio in one AR-NAR MoT. The same checkpoint also supports score editing and zero-shot covers.

Key results

  • 49.3% overall expert preference with planning vs 34.6% without
  • 6.73 SongBench Global Avg on WildSongBench, best among public baselines
  • Best-of-8 reaches 6.96 SongBench Global Avg, highest observed mean

Explicit symbolic planning improves perceived song quality while preserving a direct path to frontier full-song audio generation.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.