Paper

AREX: Towards a Recursively Self-Improving Agent for Deep Research

Uses recursive answer verification to drive targeted follow-up research, plus a learned self-updating context state for long-horizon tool use.

arXiv ↗Jul 23, 2026Code ↗

  • llm
  • agentic reasoning
  • tool use
  • long-horizon reasoning
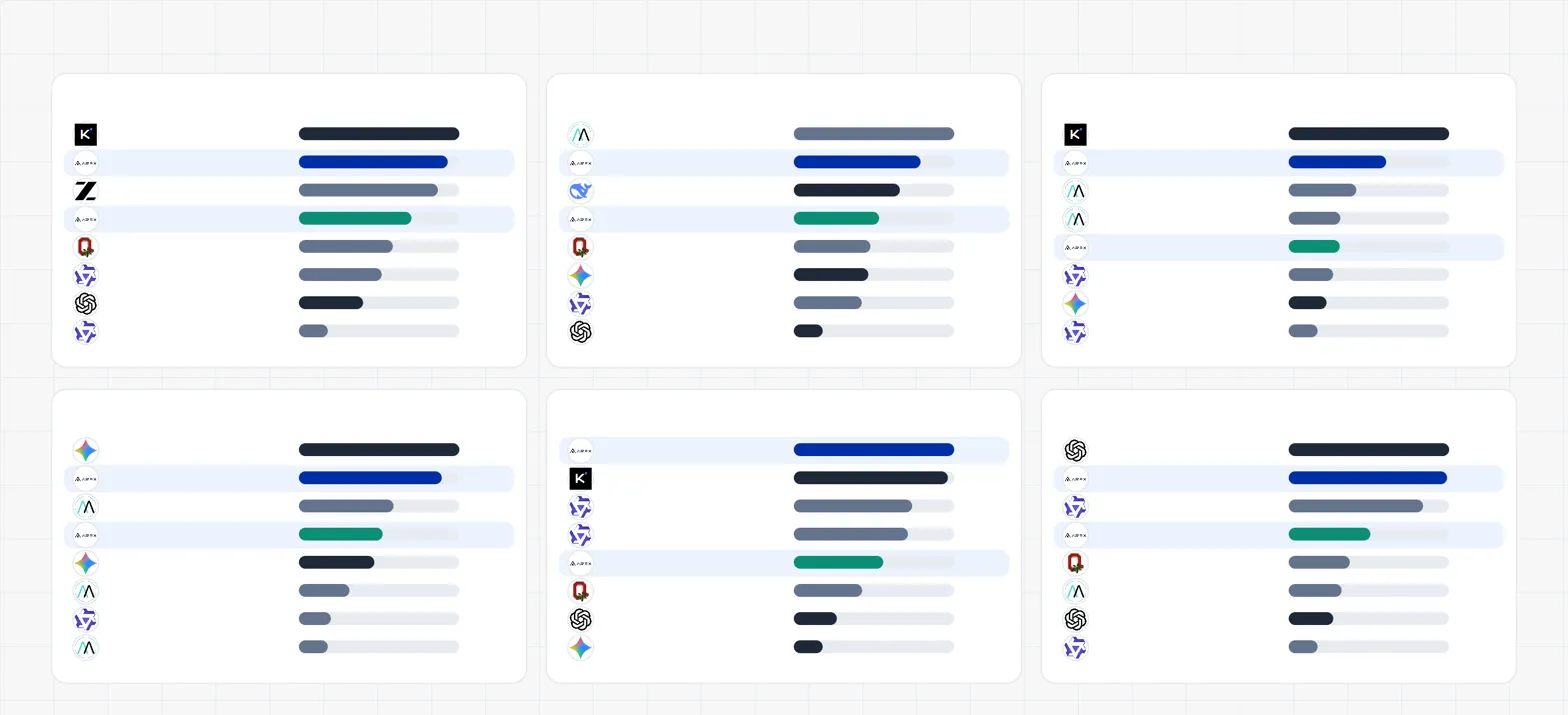
Comparative bar charts ranking models/methods across multiple panels, likely headline benchmark results

What it is

A deep-research agent that recursively audits its own provisional answers, preserves verified evidence, and launches targeted follow-up search to improve long-horizon research. Instead of only extending one search trajectory, it turns verification into control: audit a provisional answer constraint-wise, preserve verified parts, and refine or restart. It also learns its own context-update tool to compress history into a reusable research state.

Key results

  • WideSearch: 82.0, beating Kimi-K2.6 at 80.8
  • HLE: 52.4, above GLM-5 at 50.4 and Qwen-397B at 48.3
  • xbench-2510: 71.0, above Miro-1.7 at 62.0

Shows that recursively verifying and refining partial answers is more effective than simply searching longer for deep research tasks.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.