Paper

All-in-One Multilingual Scene Text Recognition with Script-aware Mixture-of-Experts

A shared-encoder, script-aware MoE recognizer routes each image to top-2 script experts plus a shared expert, avoiding per-language models and heavy VLMs.

arXiv ↗Sep 21, 2026Code ↗

  • cv
  • ocr
  • scene text recognition
  • mixture of experts
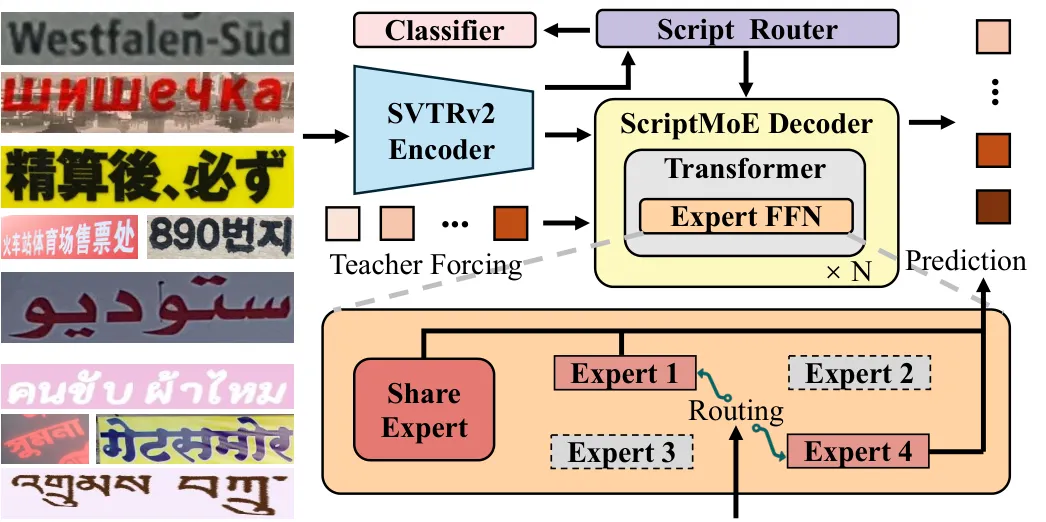
Pipeline diagram showing SVTRv2 encoder, ScriptMoE decoder with expert routing for multilingual OCR

What it is

An all-in-one multilingual scene text recognizer uses script-aware MoE decoding plus a 10M synthetic dataset to cover 10 scripts and 229 languages. Instead of one recognizer per language or a huge VLM, it uses one shared encoder with a sparse script-aware decoder: an image-level router sends each crop to top-2 script experts plus a shared expert.

Key results

  • 82.06% on TextMuSS-Bench, beating the strongest STR baseline by 1.31%
  • CC-OCR F1 improves 65.71%→80.89% by swapping in ScriptMoE
  • 80.89% CC-OCR F1 slightly beats the best VLM at 80.73%

Shows script-level sparse specialization can outperform both per-language OCR pipelines and much larger VLM recognizers in multilingual STR.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.