
What it is
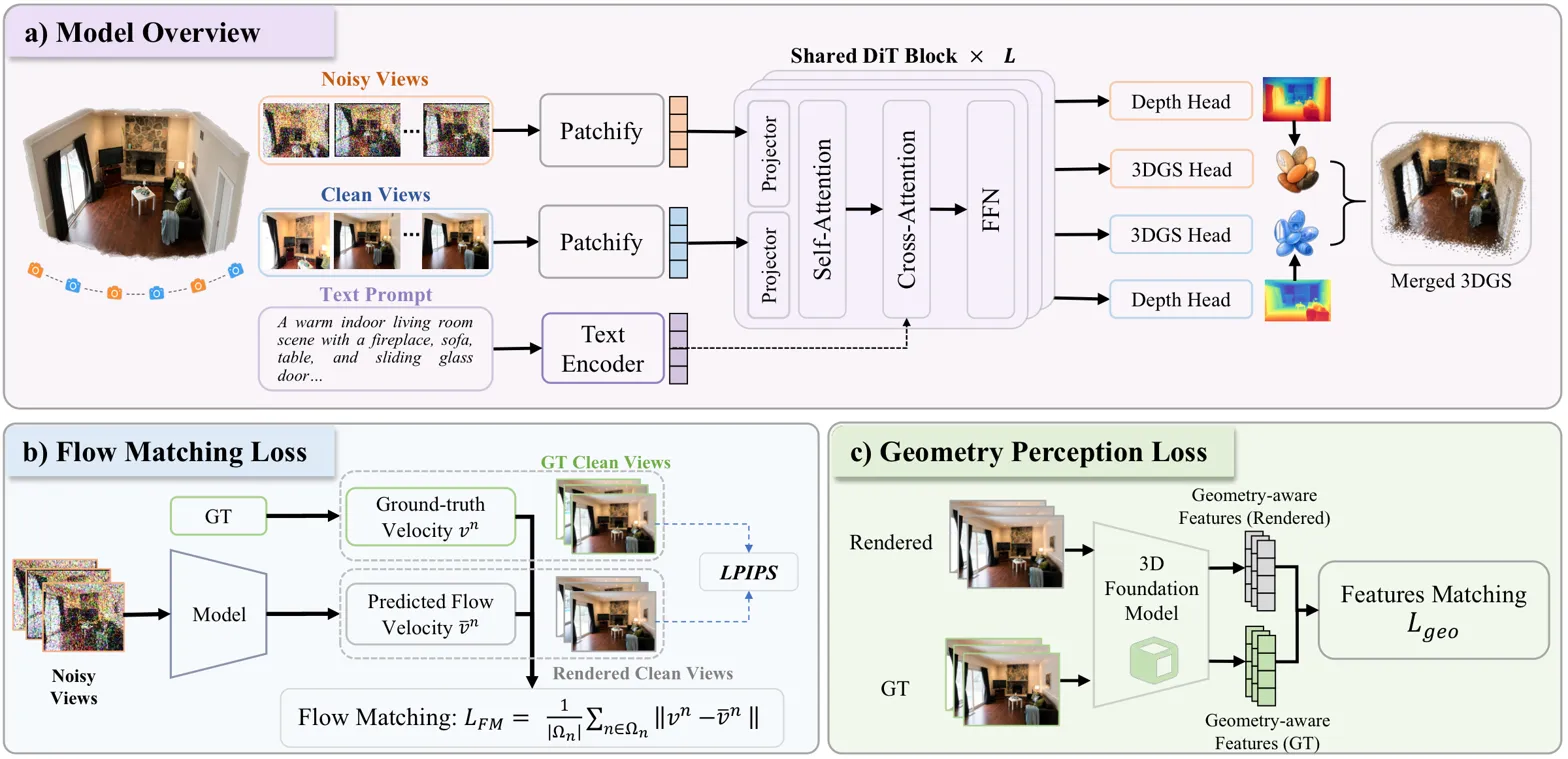
A single pixel-space diffusion model unifies 3D scene reconstruction and generation by supervising rendered views directly and adding geometry-aware 3D feature loss. Instead of latent-space diffusion with a VAE/RAE bottleneck, it diffuses in pixel space over rendered multi-view images, directly optimizing a 3D Gaussian scene; adds geometry-aware feature matching from a frozen 3D model for structural supervision.
Key results
- Re10K 1-view gen: 18.88 PSNR vs 17.59 Gen3R, 16.51 FlashWorld
- DL3DV 1-view gen: 16.50 PSNR vs 15.75 Gen3R, 15.42 FlashWorld
- Re10K 8-view recon: 28.58 PSNR vs 28.35 YoNoSplat, 27.77 DepthSplat
Direct pixel-space supervision can unify 3D generation and reconstruction without the latent bottleneck while preserving or improving scene fidelity.