
What it is
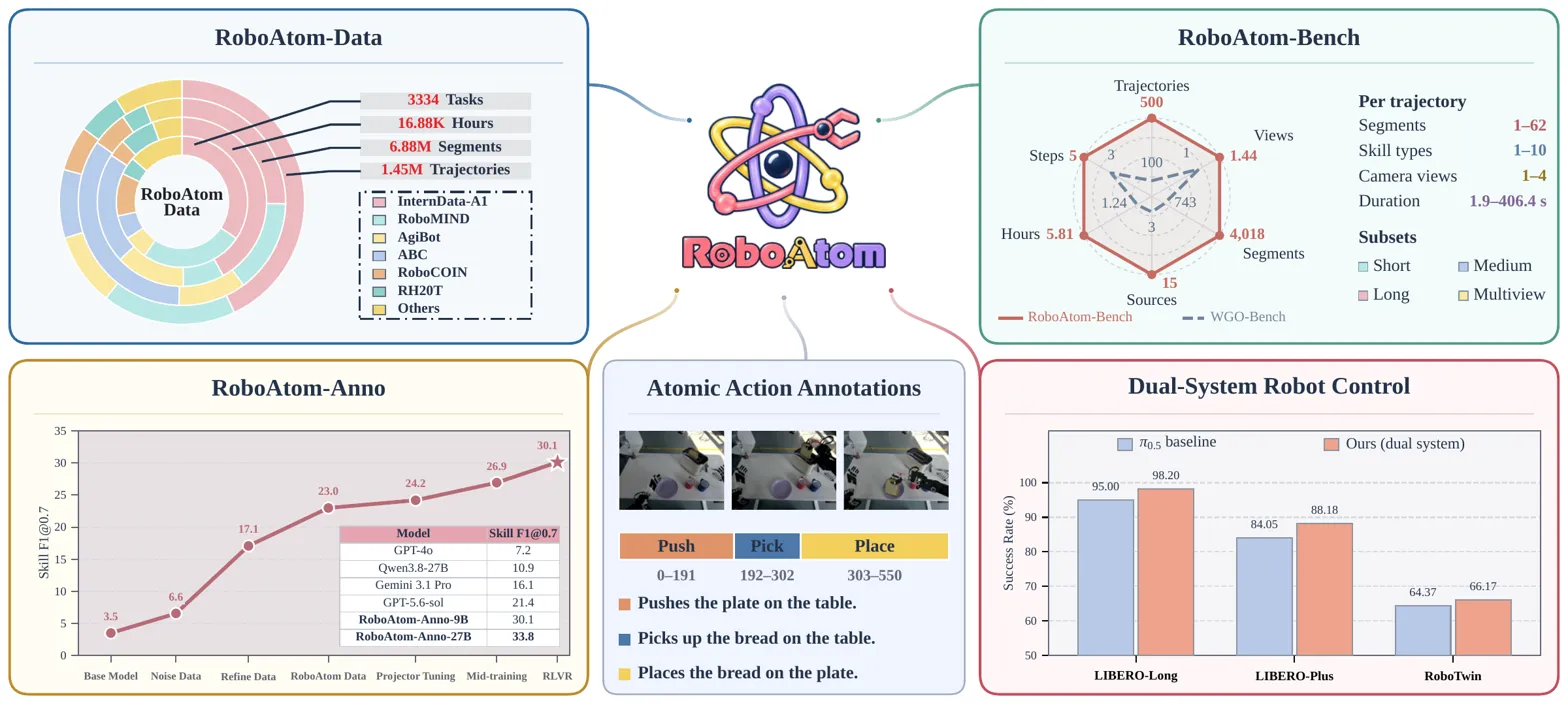
Large robot video annotation set with time-aligned atomic actions plus a 500-trajectory benchmark for temporal action segmentation and action description. 100K-1M annotation records aggregated from 12 robot datasets, with ordered segments carrying frame boundaries, one of 29 skill labels, and free-text action descriptions; plus a 500-trajectory benchmark.
Key results
- 12 source datasets in the concatenated annotation set
- 29 predefined skill labels plus unlabeled spans
- 500 benchmark trajectories with 4,018 GT segments and 721 videos
Useful for training and evaluating models that segment robot videos into atomic skills and generate action descriptions.