
What it is
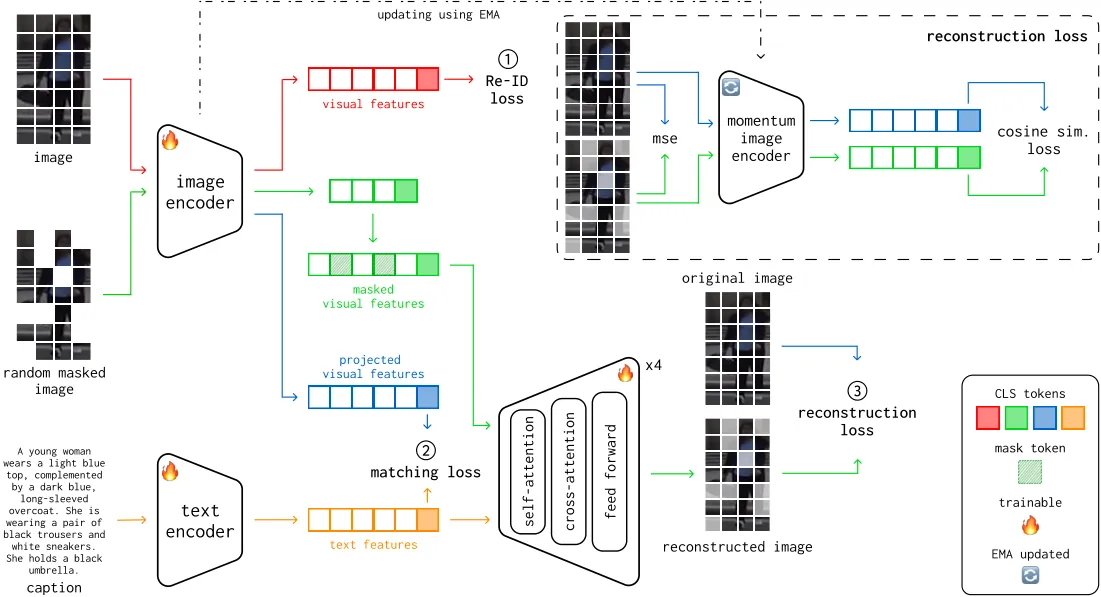
346,250 generated captions aligned to five person re-identification datasets, released as image-path and text pairs for text-augmented ReID research. 346,250 image-caption pairs across 5 multi-camera person ReID datasets. Each entry has an image_path and an auto-generated caption from LLaVA fine-tuned on UFine3C; images are not included.
Key results
- 346,250 total image-caption entries
- 5 configs: CUHK-SYSU, CUHK03, Market-1501, MSMT17, RandPerson
- 2 string fields per entry: image_path and caption
Useful for training and evaluating text-augmented person re-identification on standard benchmarks.