
What it is
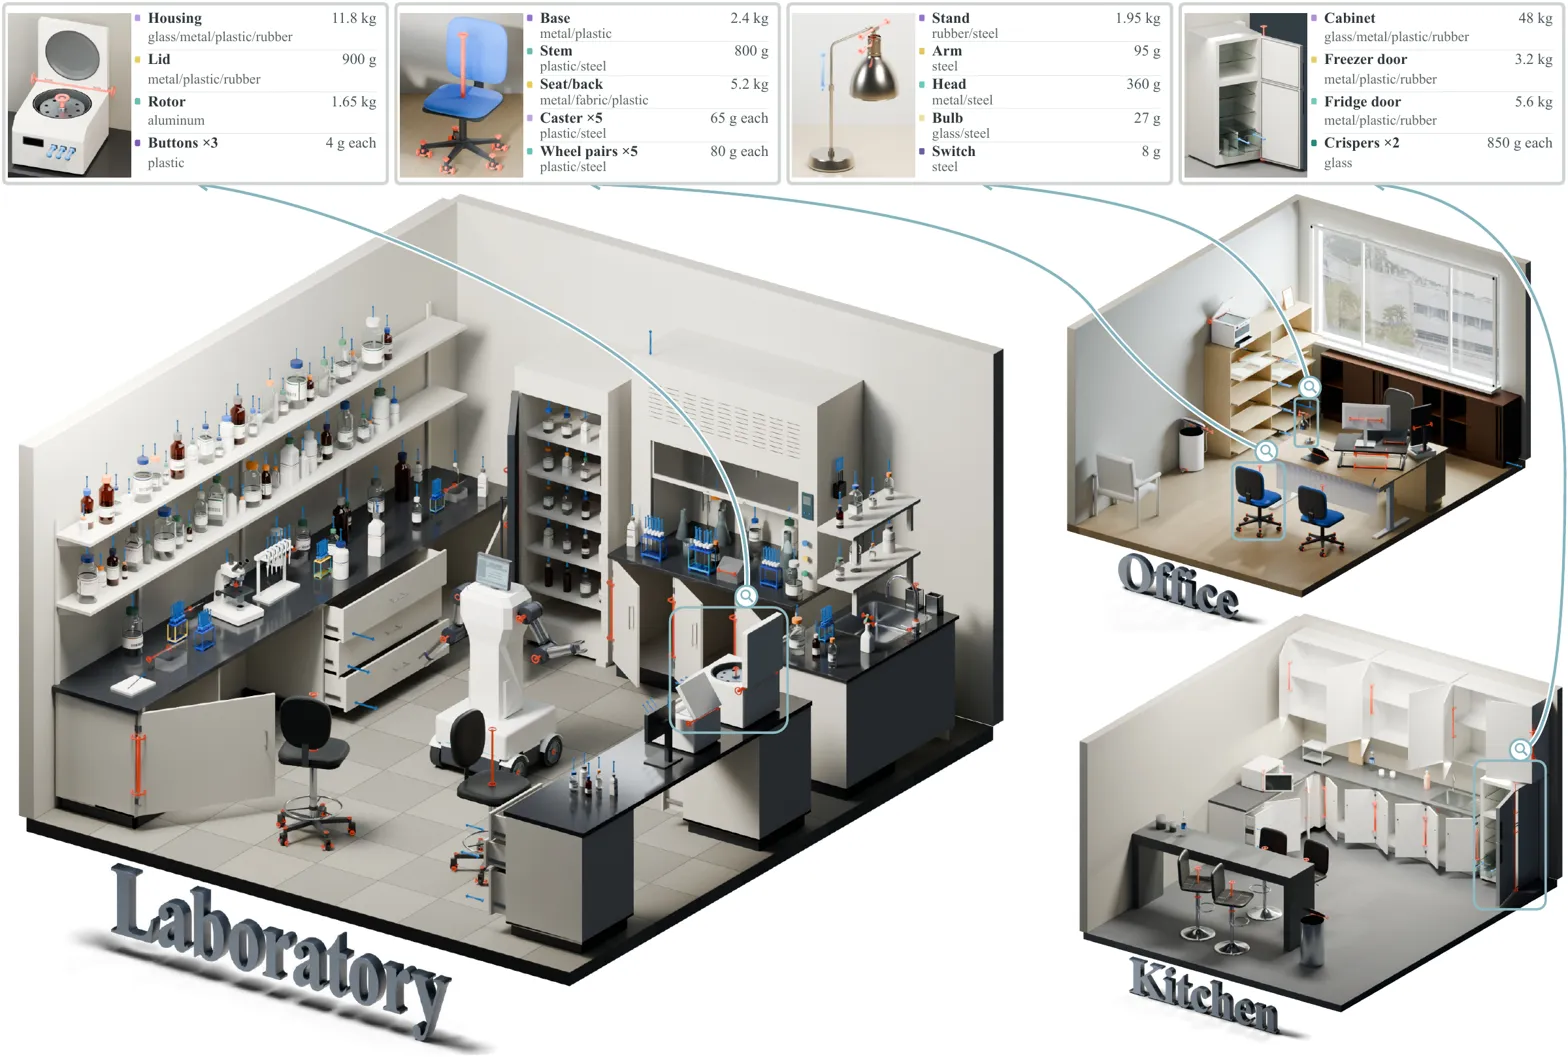
Generates articulated 3D assets from text and optional images, then benchmarks physical grounding with fidelity, collision, stability, and mass checks. Create articulated 3D assets from text and optional reference images using a multi-agent pipeline that combines procedural modeling with physical simulation feedback, then inspect and benchmark the results.
Key results
- Takes text plus optional multiple reference images as input
- Evaluates fidelity, collision, stability, and mass in one benchmark
- Supports interactive joint inspection via the built-in viewer
Shows that LLM-driven 3D asset generation can be coupled with simulation-based review to target physically grounded articulated objects.