Paper

VideoJev: System One Model for Video Understanding and Interaction

Replaces autoregressive video answers with direct scoring of interval and text candidates, then reuses one video prefix across repeated queries.

arXiv ↗Oct 13, 2026Code ↗

  • cv
  • video understanding
  • temporal grounding
  • video question answering
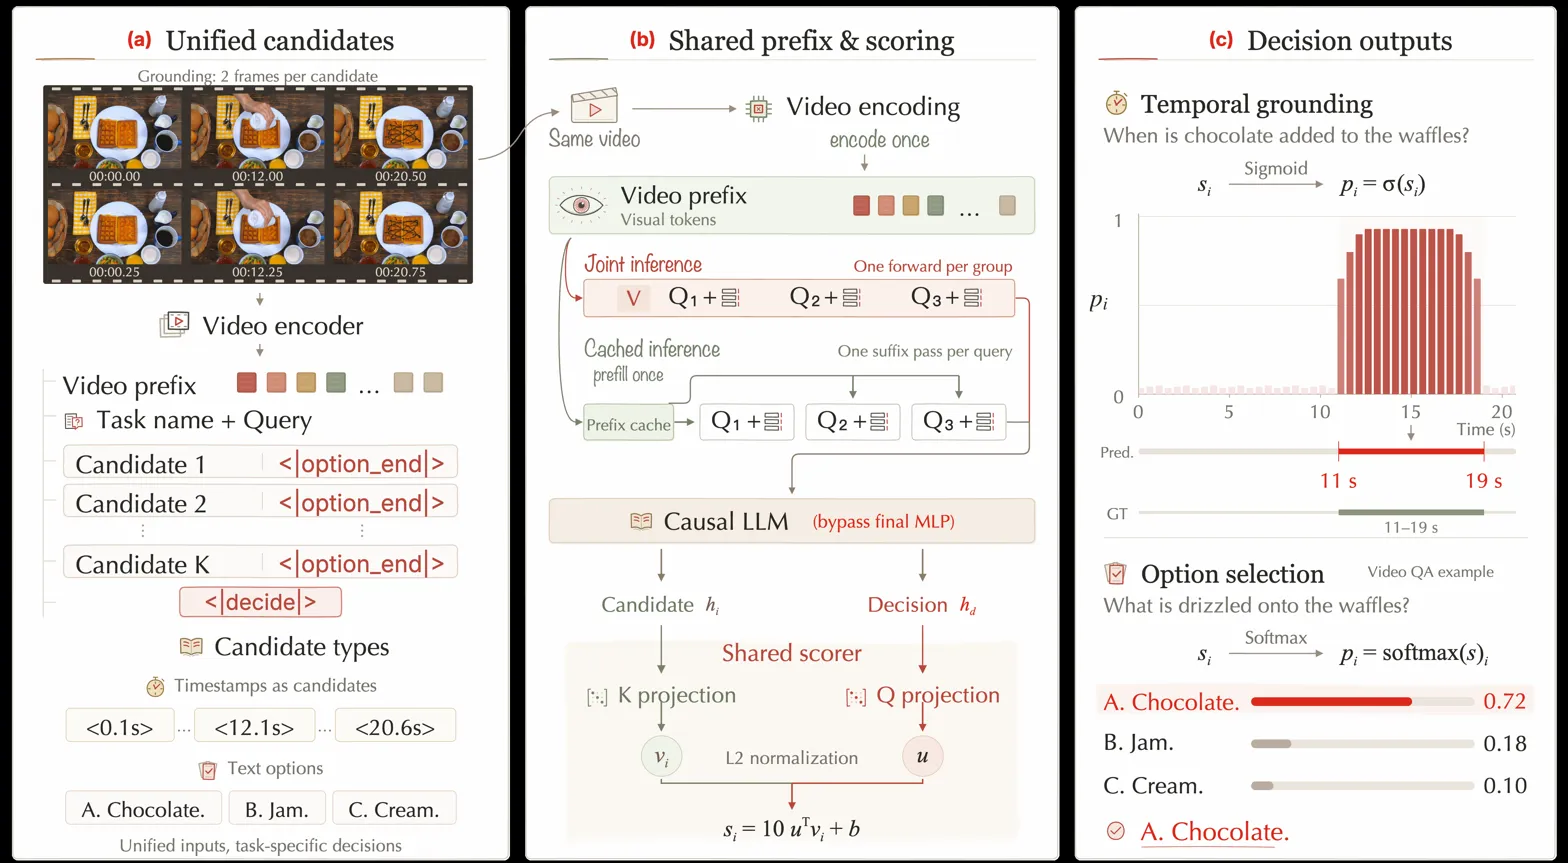
Three-panel method pipeline showing unified candidates, shared scoring, and task-specific decision outputs

What it is

Adapts video MLLMs from autoregressive generation to direct candidate scoring for temporal grounding and multiple-choice video QA, with reusable video-prefix inference. Instead of generating timestamps or answers token by token, it scores temporal intervals and answer options with one shared head over a pretrained video MLLM, then reuses the same encoded video via cached or joint inference for many queries.

Key results

  • 67.7 avg grounding mIoU, +10.8 vs Qwen3.6-35B-A3B backbone
  • 65.3 avg grounding mIoU for 4B, +6.7 vs Qwen3.5-4B backbone
  • Over 100x QA inference speedup vs Thinking baselines at comparable scores

Direct structured decisions can preserve MLLM semantic flexibility while making repeated video judgments far faster and often more accurate.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.