Paper

Player-1: Learning to Play from Synthetic Experience

A post-training pipeline that turns computer-use models into game agents by SFT on curated gameplay, then multi-env PPO on synthetic verifiable tasks.

arXiv ↗Oct 14, 2026Code ↗

  • cv
  • llm
  • multimodal
  • game agents
  • reinforcement learning
  • computer use
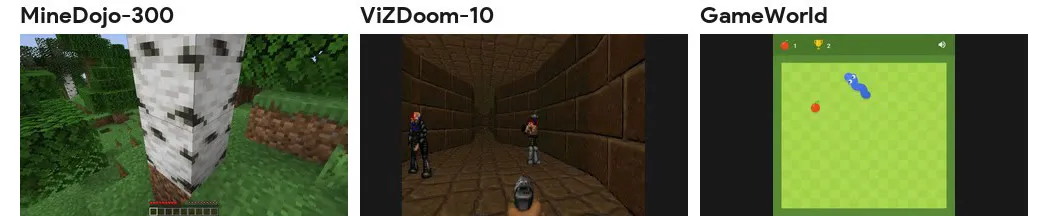
Composite showing multiple game environments the work supports across different platforms

What it is

Post-trains computer-use models for game control using synthetic RL experience in 16 verifiable environments after SFT on curated gameplay demos. Instead of relying only on demonstrations or game-specific RL, it learns transferable game control from synthetic environments built around shared control demands. It extends CUA actions with relative mouse motion, holds, and composite inputs, then PPO-trains on verifiable rewards.

Key results

  • 38.33% on MineDojo-300 for 9B vs 10.54% SFT and 12.63% best baseline
  • 41.04% on MineDojo-300 for 35B-A3B vs 23.38% SFT
  • MineDojo coverage at >=4/8 successes rises from 20 to 136 tasks for 9B

Shows that synthetic RL environments organized by shared control skills can transfer to held-out real games beyond demonstration-only training.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.