
What it is
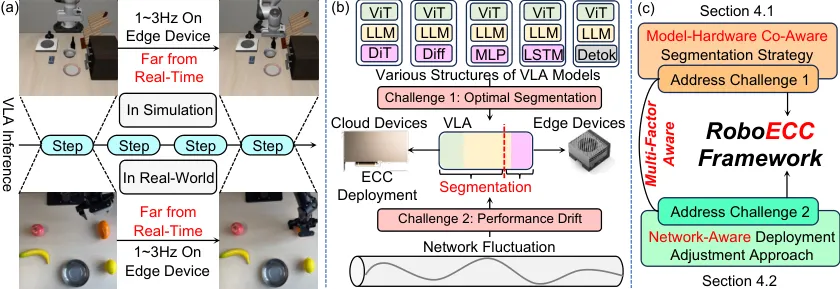
Planner and runtime-control layer for splitting VLA inference across edge and cloud, with offline cut search and online bandwidth-aware adjustment. Chooses where to split VLA inference between edge and cloud, then adjusts the cut online using hardware, cloud-load, activation-size, and bandwidth signals.
Key results
- 3.16×–3.28× speedup on Orin+A100 vs edge-only
- 2.10×–2.23× speedup on Thor+A100 with 2.55%–2.62% overhead
- No third-party runtime deps for core planner; optional Torch only for LSTM
Shows that VLA deployment can benefit from dynamic edge-cloud partitioning with low reconfiguration overhead.