Paper

FrontierChallenge: Evaluating Scientific Workflow Completion

Evaluates scientific agents by full workflow contract satisfaction, using executable graders over multi-artifact deliverables instead of answer-only scoring.

arXiv ↗Aug 25, 2026

  • llm
  • nlp
  • benchmarks
  • agents
  • scientific workflows
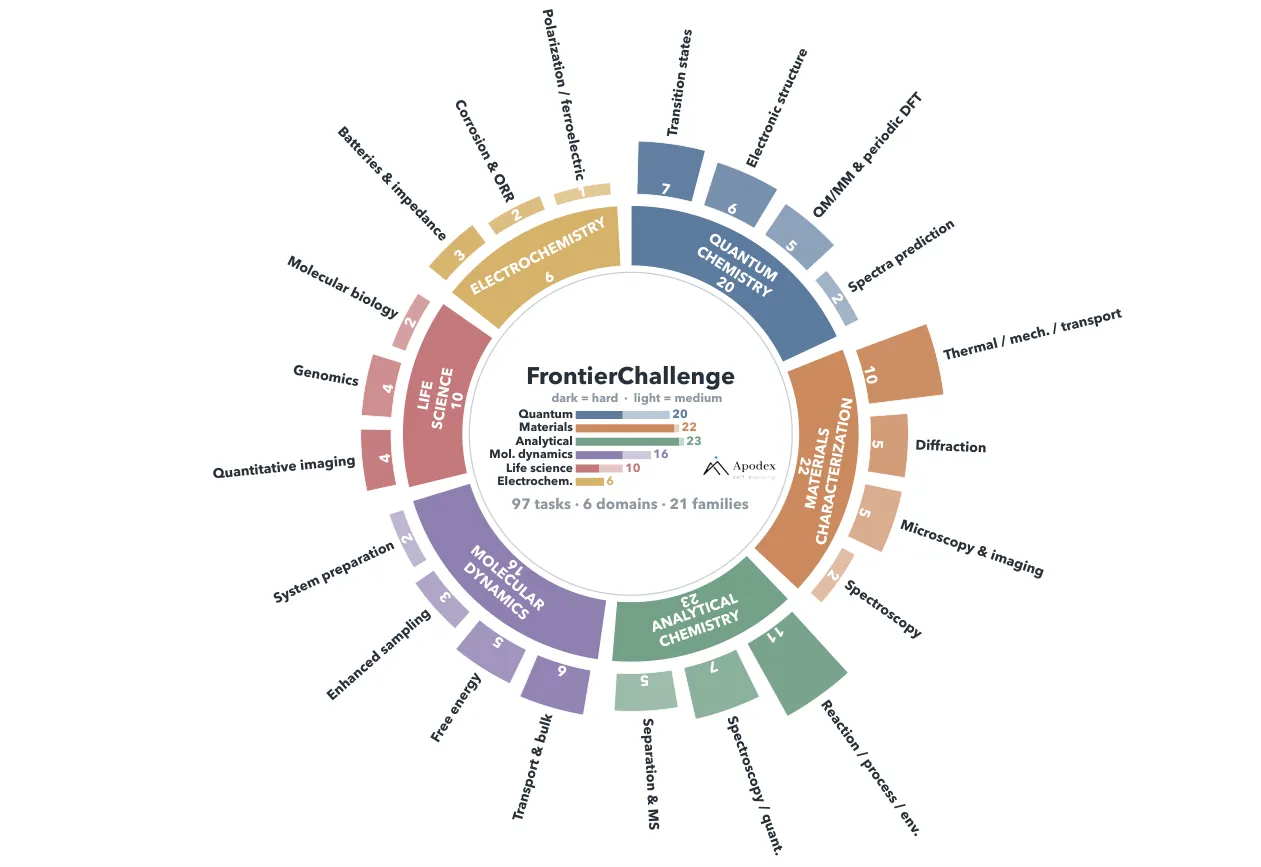
Taxonomy sunburst characterizing dataset: 97 tasks, 6 domains, 21 families with counts

What it is

A benchmark for end-to-end scientific workflow completion across domains, scoring full artifact delivery rather than partial progress or final answers. Shifts evaluation from answers or single programs to contract-level workflow completion: fixed scientific inputs, multi-artifact deliverables, and task-specific executable graders across 97 cross-domain tasks.

Key results

  • Best Pass Rate is 20.6%: GPT-5.6 Sol/Codex and Grok 4.6/Claude Code
  • Highest Avg. Score is 87.9 for GPT-5.6 Sol/Codex, yet only 20.6% pass
  • Electrochemistry peaks at 94.9 Avg. Score but 0% Pass Rate for all configs

Shows that high partial-credit scores and confident completion claims do not reliably mean a scientific workflow was actually finished.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.