
What it is
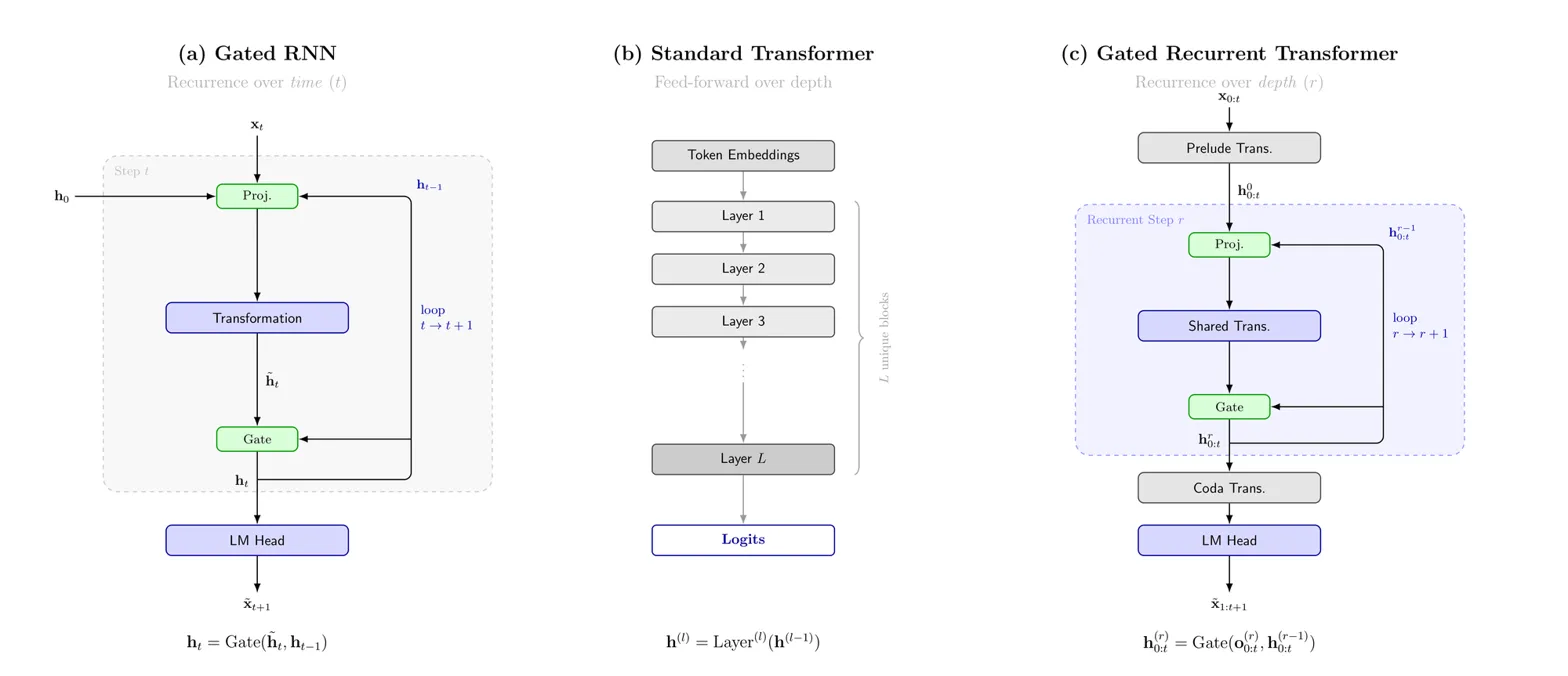
A recurrent-depth transformer that reuses a shared core but modulates each pass with gating, matching dense GPT-2 quality with far fewer parameters. Instead of plain weight sharing that applies the same layer repeatedly, it adds a fixed prelude/coda plus a gated shared core. The gate conditions on current state and input anchor so the same weights act like specialized layers across recurrences.
Key results
- 3-layer GRT matches 12-layer GPT-2 Small at isoFLOPS: 3.14 vs 3.15
- Beats RRT at medium and large isoFLOPS: 2.89 vs 2.95, 2.77 vs 2.85
- At isoPARAMS large scale, improves val loss to 2.65 vs 2.71 dense baseline
Adaptive gating makes depth reuse viable: shared layers can recover much of dense-layer specialization while cutting parameters and memory.