
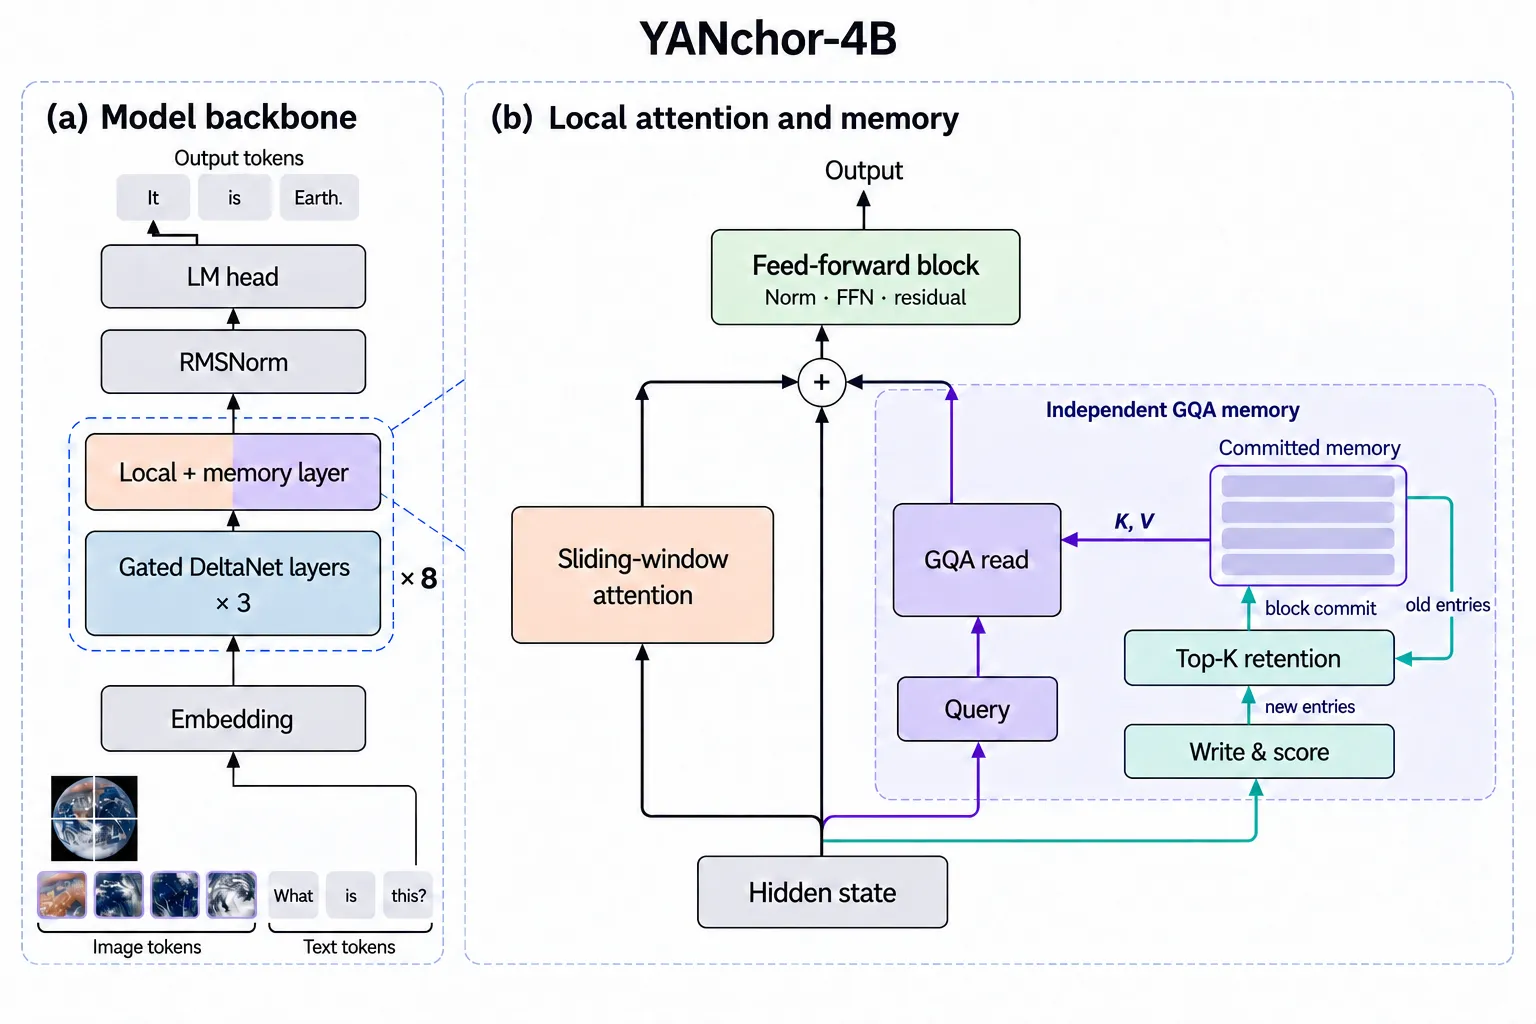
What it is
Recurrent 4B LLM for long-horizon reasoning with O(N) generation and O(1) history-state memory, plus an H100 runtime that sustains long-context batching. Run long-context reasoning with fixed history-state memory using a recurrent 4B model that stores retrievable memory anchors, plus serving and evaluation code for H100 deployment.
Key results
- 12,431 end-to-end tok/s at 32K in + 32K out on one H100
- Fixed 48.90 GiB history cache from 512 to 65,536 tokens for 512 seqs
- 77.2 mean on 29 text benchmarks; 82.9 on AIME 2024-2026
Shows a bounded-state recurrent LLM can retain strong general reasoning while scaling long generation with constant history-state memory.