Paper

DiffusionART: Efficient, Stable and Scalable Reinforcement of Diffusion Models

Replaces NFT's unstable forward reward targets with prompt-level aggregated guidance on reverse states, plus a second restoration update without EMA tuning.

arXiv ↗Oct 8, 2026Code ↗

  • llm
  • multimodal
  • diffusion models
  • reinforcement learning
  • text-to-video
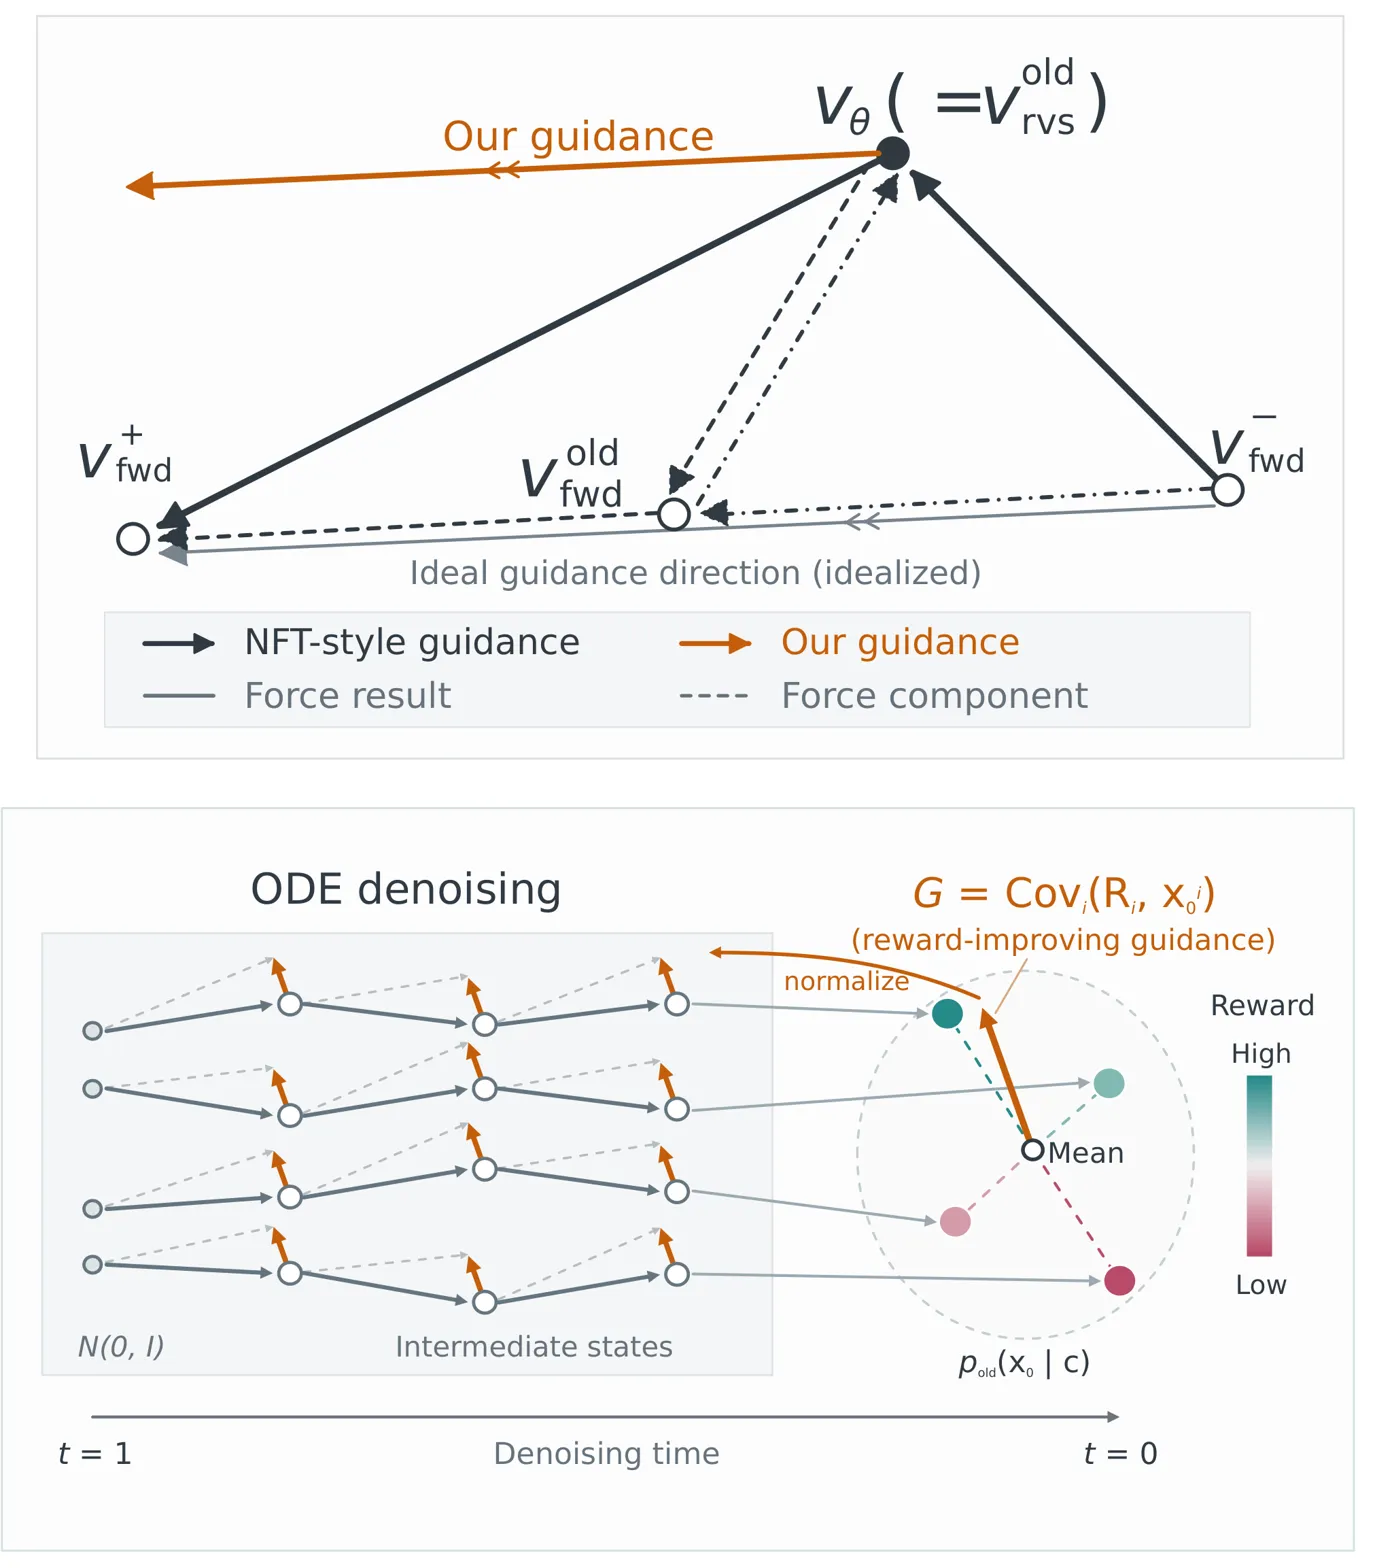
Method diagram showing guidance mechanism and ODE denoising with reward-improving guidance

What it is

An online RL method for diffusion models that replaces unstable NFT-style reward regression with aggregated prompt-level guidance plus adaptive restoration. Instead of NFT's forward-process targets and EMA tuning, it aggregates per-prompt rewards into one shared reward-improving direction for reverse-rollout states, then adds a trust-region-masked second update for drift-adaptive restoration.

Key results

  • 12.02x fewer GPU hours than DiffusionNFT at matched late-stage reward
  • 11.72x fewer GPU hours than Flow-GRPO-Fast at matched late-stage reward
  • Mean training reward is 28.8% above DiffusionNFT and 53.0% above Flow-GRPO-Fast

Prompt-level reward aggregation can keep diffusion RL efficient while removing the instability that NFT handled with tuned EMA.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.