Paper

EchoWM: Open and Enterable Omnimodal World Models

A unified trajectory-controlled world model that natively generates synchronized video, env sound, music, and speech for first- and third-person interaction.

arXiv ↗Aug 24, 2026Code ↗

  • multimodal
  • world models
  • video generation
  • audio-visual generation
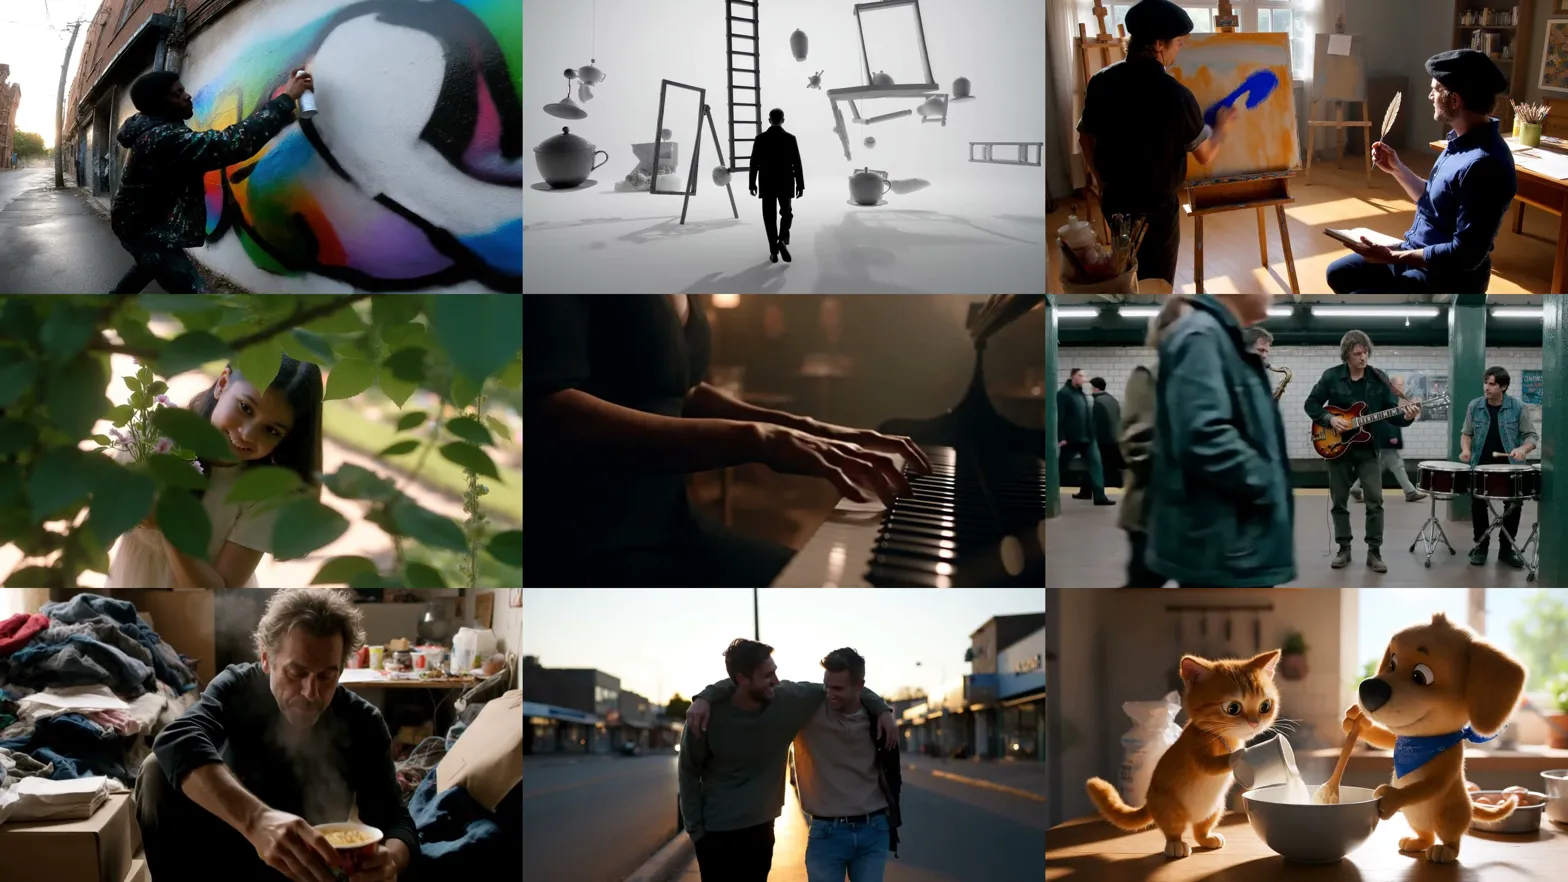
Curated grid of diverse generated samples showing model's output variety

What it is

An omnimodal world model that turns video generation into a navigable world, jointly producing 720p video, environmental audio, music, and speech from trajectory control. Unlike prior world models that are mostly visual or use domain-specific controls, it uses one camera-intent interface: discrete commands and poses map to a shared metric 6-DoF trajectory for both first- and third-person audio-visual generation.

Key results

  • #1 on WBench Navigation
  • Top-tier visual quality on SANA-WM-Bench simple and hard splits
  • Supports 720p long-horizon generation with synchronized sound and speech

A single camera-centric 6-DoF control interface can span first- and third-person interactive world generation without separate view-specific controllers.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.