
What it is
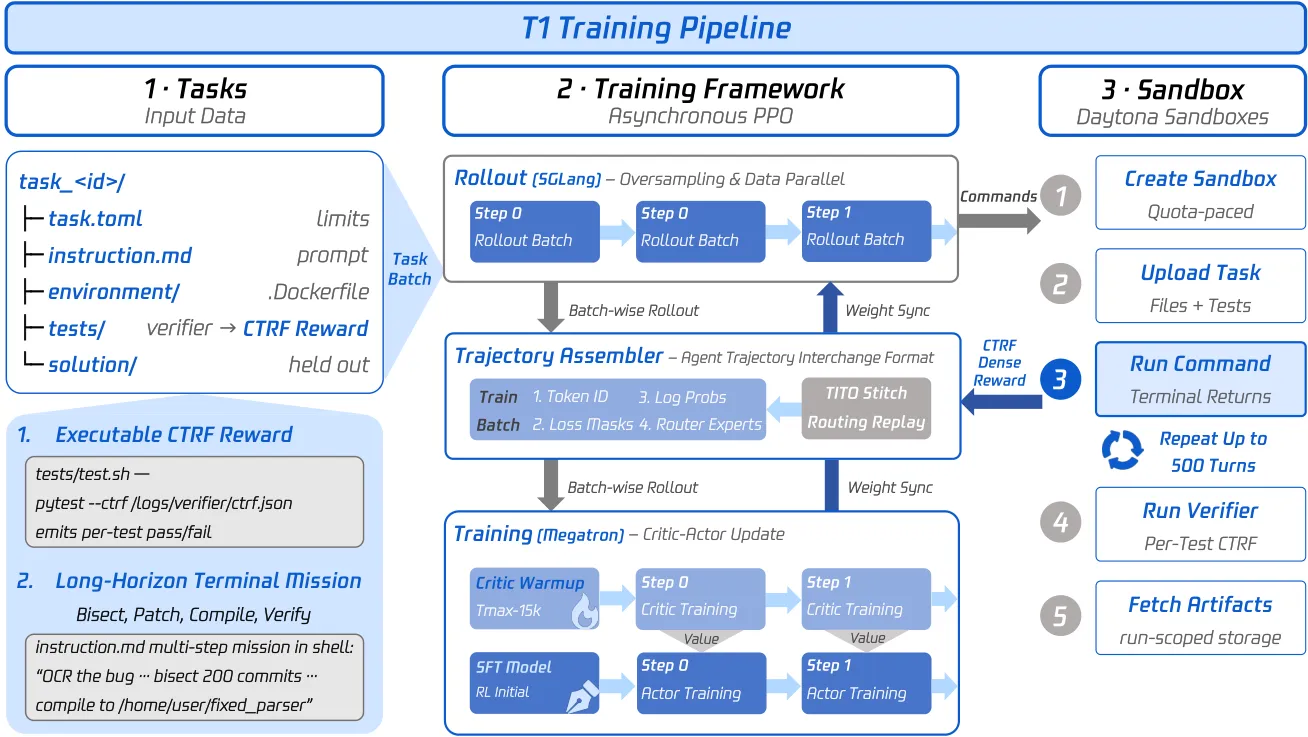
RL-trains a 122B MoE terminal agent for 300+ turn shell tasks using executable verifiers, plus a stability stack that aligns training with sampled tokens and MoE routing. Instead of RL on text-only or short-horizon agents, it trains a real-shell MoE agent with executable verifier rewards. The key difference is a stability recipe for sparse RL: exact sampled-token training (TITO), replayed MoE routing (R3), and dense per-assertion rewards.
Key results
- 64.0% on Terminal-Bench 2.1, up from 43.8% base
- Beats GPT-5.4 54.8% and V4-Flash 56.9% on Terminal-Bench 2.1
- 27.9% on Long-Horizon Terminal Bench, above GPT-5.4 and GLM-5.1
Shows that long-horizon terminal capability can be improved substantially with verifier-based RL if token and MoE routing mismatch are explicitly controlled.