Repo

Atria-Dawn-Preview

Solves multi-step agent tasks with tool use, coding, and execution loops. Supports 256K context and local deployment via SGLang or vLLM.

GitHub ↗Sep 12, 2026

  • llm
  • agentic-model
  • tool-use
  • coding
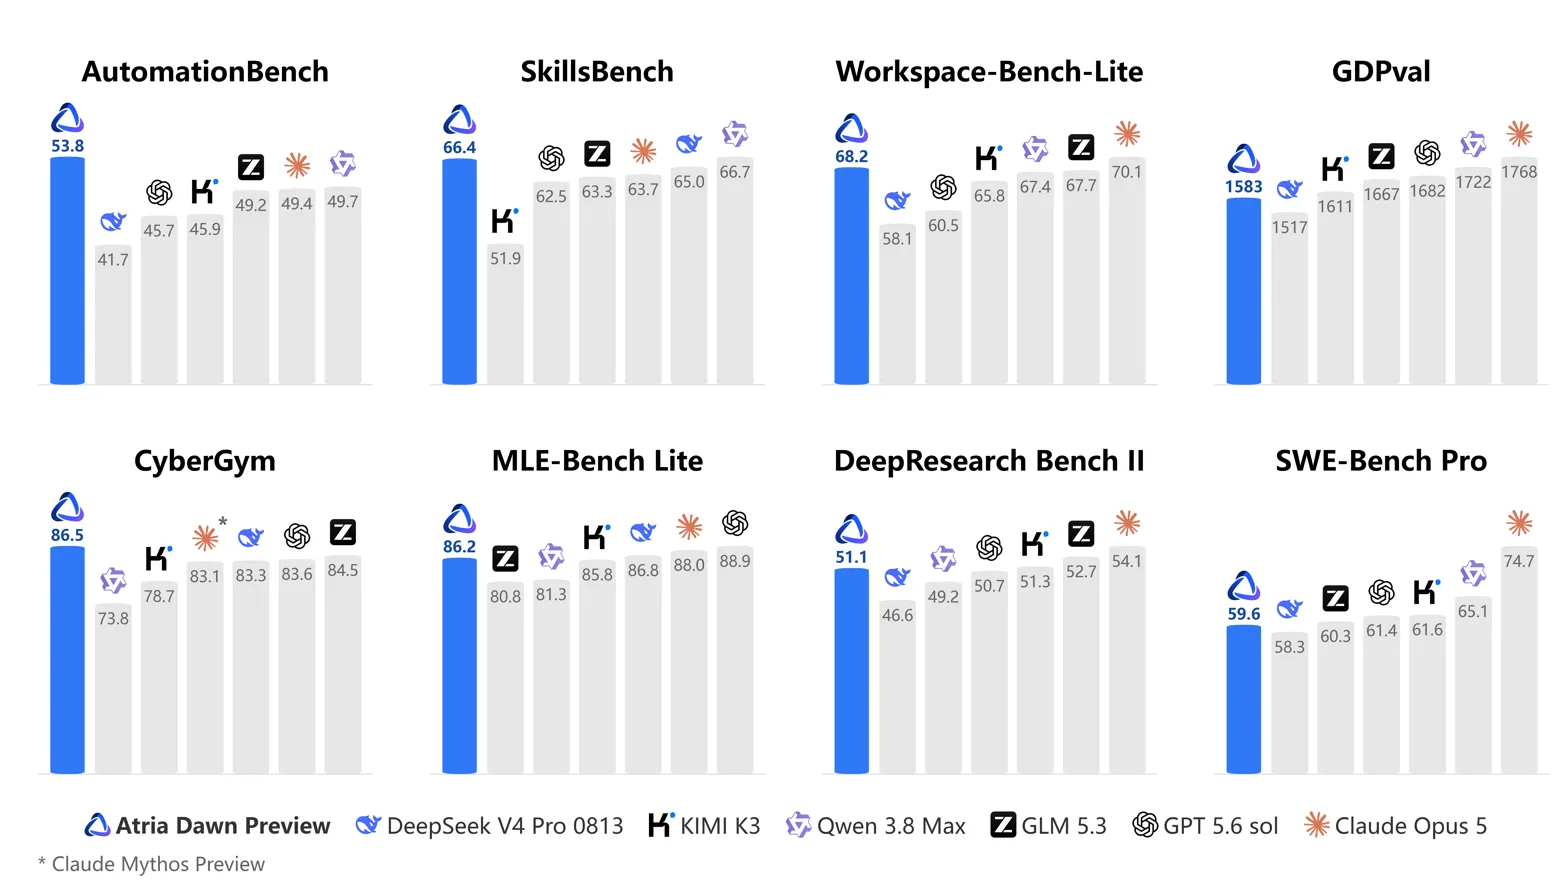
Headline benchmark comparison of Atria Dawn vs baselines across eight benchmarks

What it is

Agentic 744B MoE model for research and engineering workflows, optimized for tool use, coding, and verifiable multi-step execution. Handles open-ended research and engineering tasks end to end, from planning and tool use to code execution, result analysis, and failure recovery, with local or hosted deployment.

Key results

  • Best reported on DeepSearchQA with 96.0 and BrowseComp with 92.5
  • Best reported on BFCL v4 at 77.0 and AutomationBench at 53.8
  • 256K context; deployable with SGLang v0.5.13.post1+ or vLLM v0.23.0+

Shows that open agentic models can compete across research, coding, productivity, and security benchmarks in one system.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.