
What it is
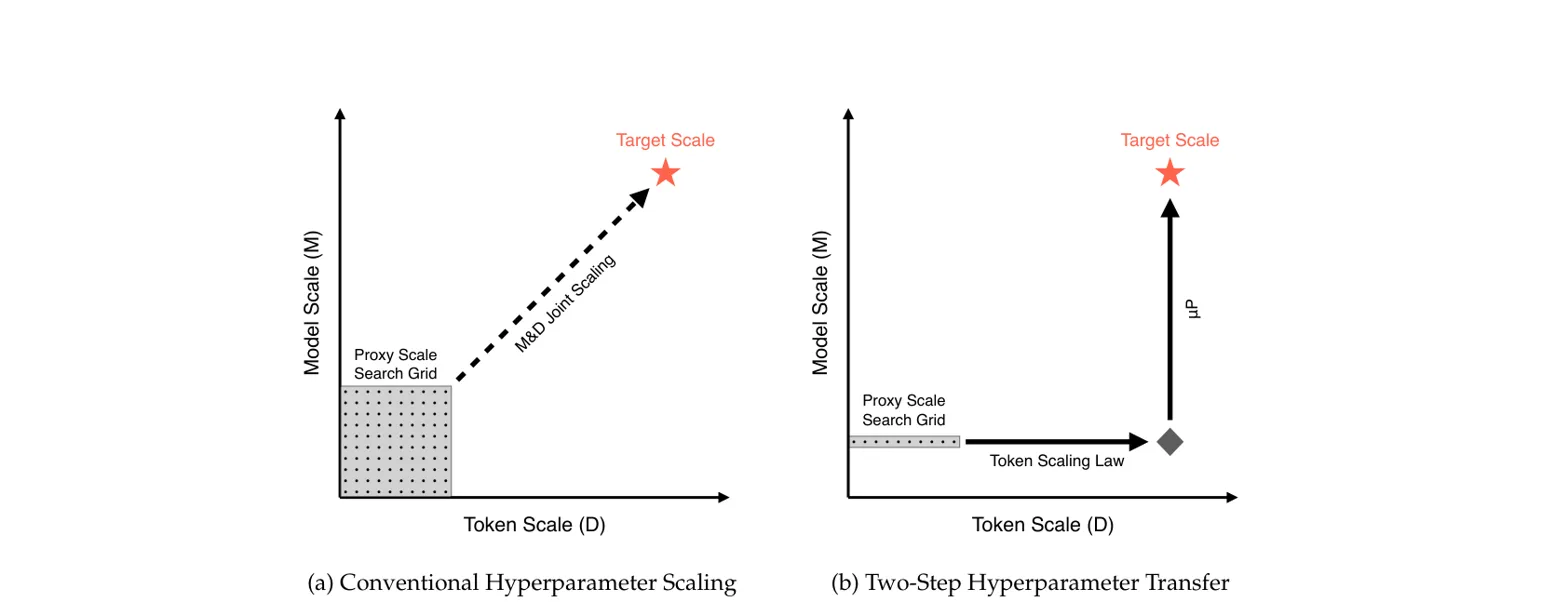
Predicts the best learning rate for huge MoE pretraining from small proxy runs by transferring across width with μP, then extrapolating across token budget with a scaling law. Instead of costly 2D sweeps over model and token scale, transfer the optimal LR across width-scaled MoEs with μP, then fit a token-scaling law from short proxy runs to extrapolate LR to trillion-token training.
Key results
- Optimal LR extrapolation to 10T tokens reaches R^2=0.95
- Target 155B/17B-active training used about 98× the compute of proxy runs
- 2D model-scale sweeps add 240.3 ZFLOPs beyond the 64.8 ZFLOP proxy search
Shows that small proxy MoEs can reliably set learning rates for much larger, much longer MoE pretraining when width transfer and token extrapolation are decoupled.