
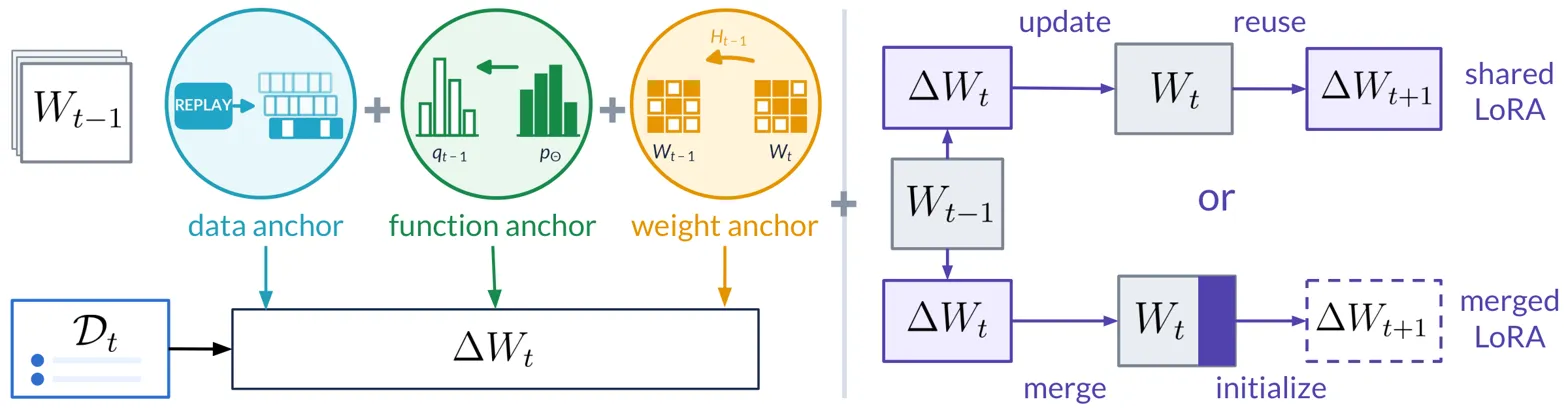
What it is
Studies 100-task continual QA memorization in LMs and shows that combining replay, self-distillation, weight regularization, and merged LoRA greatly reduces forgetting. Instead of seeking one best continual-learning trick, it composes complementary anti-forgetting mechanisms: data, function, and weight anchors, plus merged LoRA to isolate successive updates.
Key results
- 34.9% avg final retention vs 1.2% for naive sequential fine-tuning
- Best single mechanism gets 8.1%; full composition reaches 34.9% avg
- Top composition ranks among top 3 methods on all 3 100-task datasets
Long-horizon LM memory benefits most from combining complementary retention constraints with explicit low-rank update allocation.