Paper

An Open Recipe for IMO Gold: Training Nemotron for Olympiad Mathematics

A multi-checkpoint natural-language proof search uses specialist SFT/RL models to generate, verify, refine, and finally rank IMO solutions.

arXiv ↗Sep 9, 2026Code ↗Dataset ↗

  • llm
  • mathematical reasoning
  • test-time compute
  • reinforcement learning
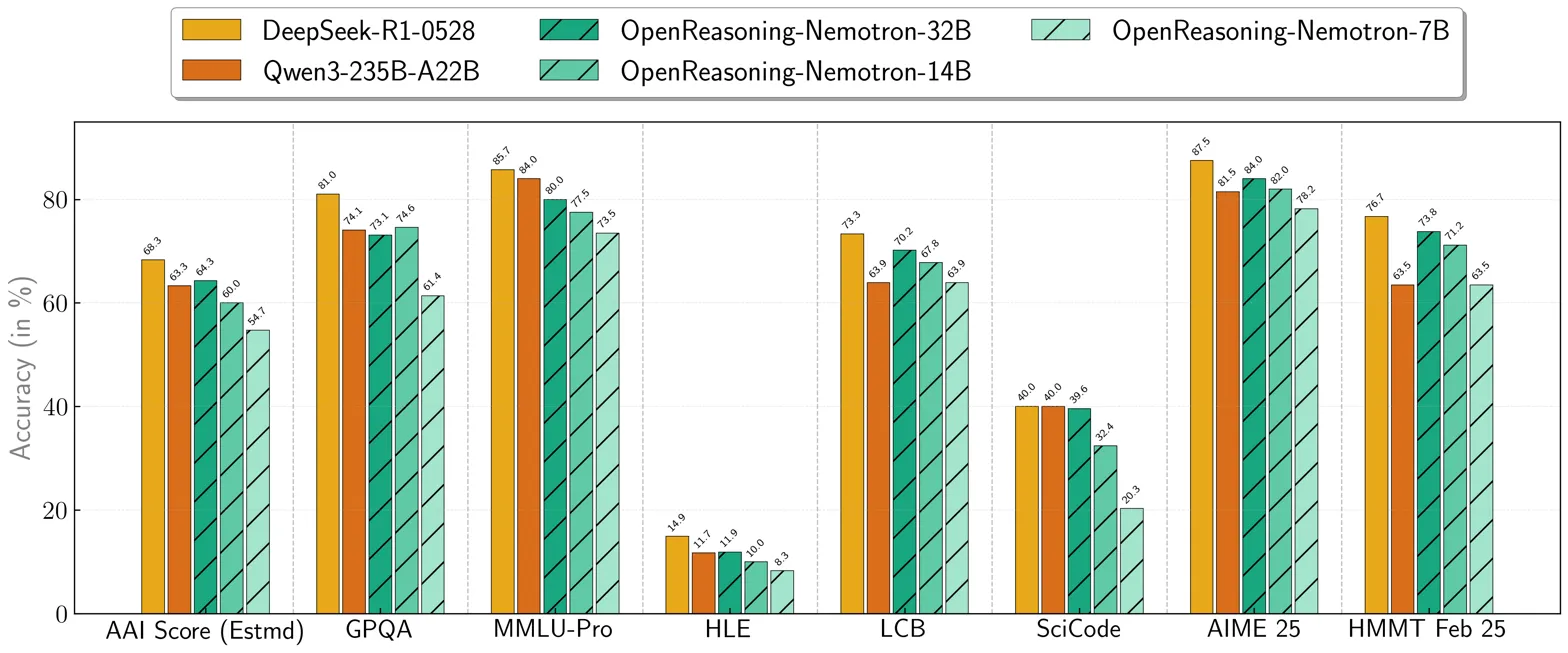
Headline benchmark comparison of OpenReasoning-Nemotron models vs baselines across multiple tasks

What it is

Open natural-language IMO solver built from post-trained Nemotron checkpoints plus high-compute generate-verify-refine search. It reached IMO 2026 gold without formal tools. Instead of relying on formal provers or a single model, it combines SFT- and RL-specialized Nemotron checkpoints in an iterative natural-language search that generates, verifies, refines, then re-ranks proofs with heavy test-time compute.

Key results

  • 30/42 at IMO 2026, beating the 29-point gold-medal cutoff
  • Full credit on Problems 1, 2, 4, and 5; 1 point each on 3 and 6
  • RL eval accuracy rose to about 58% on a 133-problem proof set

Shows open-weight LLMs can reach IMO gold with specialist post-training and aggressive verifier-guided test-time search, even without formal tools.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.