Paper

On-Policy Self-Distillation in Diffusion Models

Converts endpoint reward into explicit clean-output targets at on-policy denoising queries, then trains by fitting those detached targets instead of backpropagating reward through rollouts.

arXiv ↗Aug 25, 2026Code ↗

  • cv
  • diffusion models
  • reinforcement learning
  • image generation
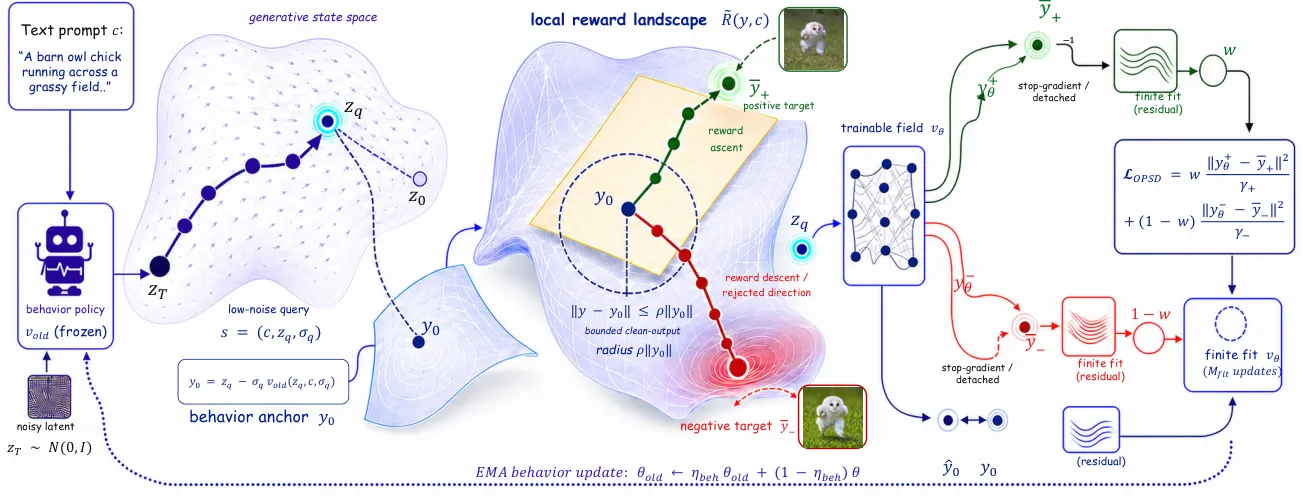
Detailed method pipeline showing reward landscape, trainable field, and loss computation

What it is

An on-policy self-distillation method for diffusion post-training that turns image-level rewards into explicit intermediate denoising targets. Instead of implicit RL credit or endpoint reweighting, it builds bounded positive/negative clean-output targets from reward gradients at sampled denoising states, then fits them as detached supervision and refreshes targets on-policy via EMA.

Key results

  • Best held-out score in 19 of 20 matched settings across 2 backbones
  • Up to 44.0% better than the strongest competing method
  • Cuts training GPU-hours vs DiffusionNFT by 40% on SD3.5-M, 63% on Z-Image-Turbo

Explicit on-policy target construction makes diffusion reward alignment both more efficient and easier to diagnose than implicit reward-driven updates.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.