Paper

SWE-Bench ProMax: Benchmarking Agents on Large-Scale Multilingual Code Refactoring

A benchmark centered on large real-world refactors, not saturated bug-fix tasks, with rewritten issue specs and manually reviewed tests to improve evaluation quality.

arXiv ↗Aug 10, 2026Code ↗Dataset ↗

  • llm
  • code agents
  • benchmarking
  • software engineering
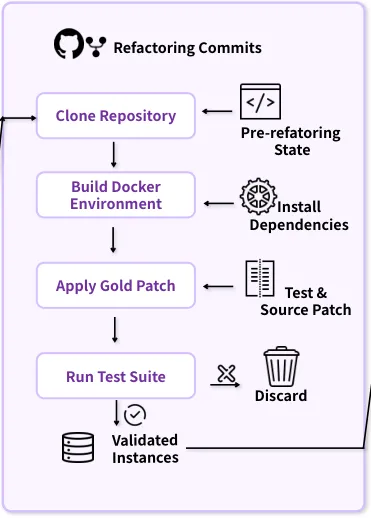
Pipeline diagram showing refactoring commits processing workflow from clone to validation

What it is

An expert-curated benchmark for large, multilingual code refactoring tasks that fixes test/spec flaws in prior SWE benchmarks and remains unsaturated for current agents. Instead of mostly single-file bug-fix tasks with flawed tests, it benchmarks behavior-preserving refactors from real commits, with rewritten specs and manually cleaned tests across 7 languages.

Key results

  • Best model reaches only 41.2% resolve rate on 170 tasks
  • Tasks average 11.4 modified source files and 261.6 LOC
  • 30% of tasks modify >10 files; 32% change >200 LOC

Current coding agents still struggle mainly with cross-file coordination on large, behavior-preserving refactors.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.