
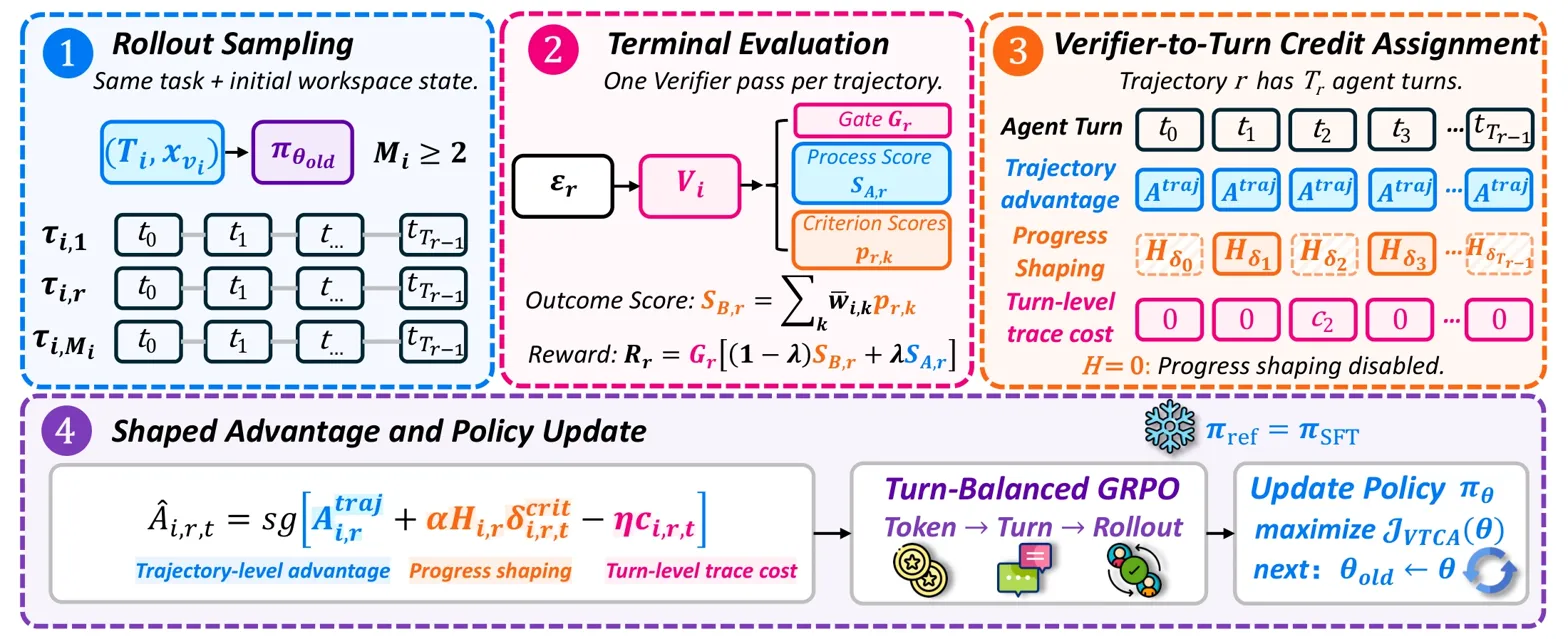
What it is
Trains long-horizon cowork agents by recursively repairing synthesized work environments and adding verifier-grounded turn credit during RL. Instead of one-shot task generation and episode-only rewards, it recursively repairs misaligned context/task/verifier packages and adds verifier-grounded turn credit from workspace progress.
Key results
- +413.25 Elo on GDPval v2 over Qwen3.5-35B-A3B
- JobBench improves by 26.27 points over Qwen3.5-35B-A3B
- FCR raises task-package synthesis pass rate by 6.0 points vs regeneration
Shows long-horizon agent RL improves when training environments are iteratively repaired and rewards are grounded in verified intermediate workspace progress.